My DuckDB extensions: caching, storage, and everything around remote data
DuckDB is fast on a laptop SSD. Point it at S3 and you’re dealing with round trips, tail latency, throttling and egress bills instead.
In November 2024, a DuckDB user opened an issue on httpfs asking for a disk cache: querying S3 from a laptop was slow, and every query paid for egress again. That issue is still open. Four months later I shipped cache_httpfs as a community extension. In the latest published rolling week, it was downloaded 56,068 times, sixth among 356 community extensions with reported downloads (snapshot updated October 12, 2026, 04:00 UTC).
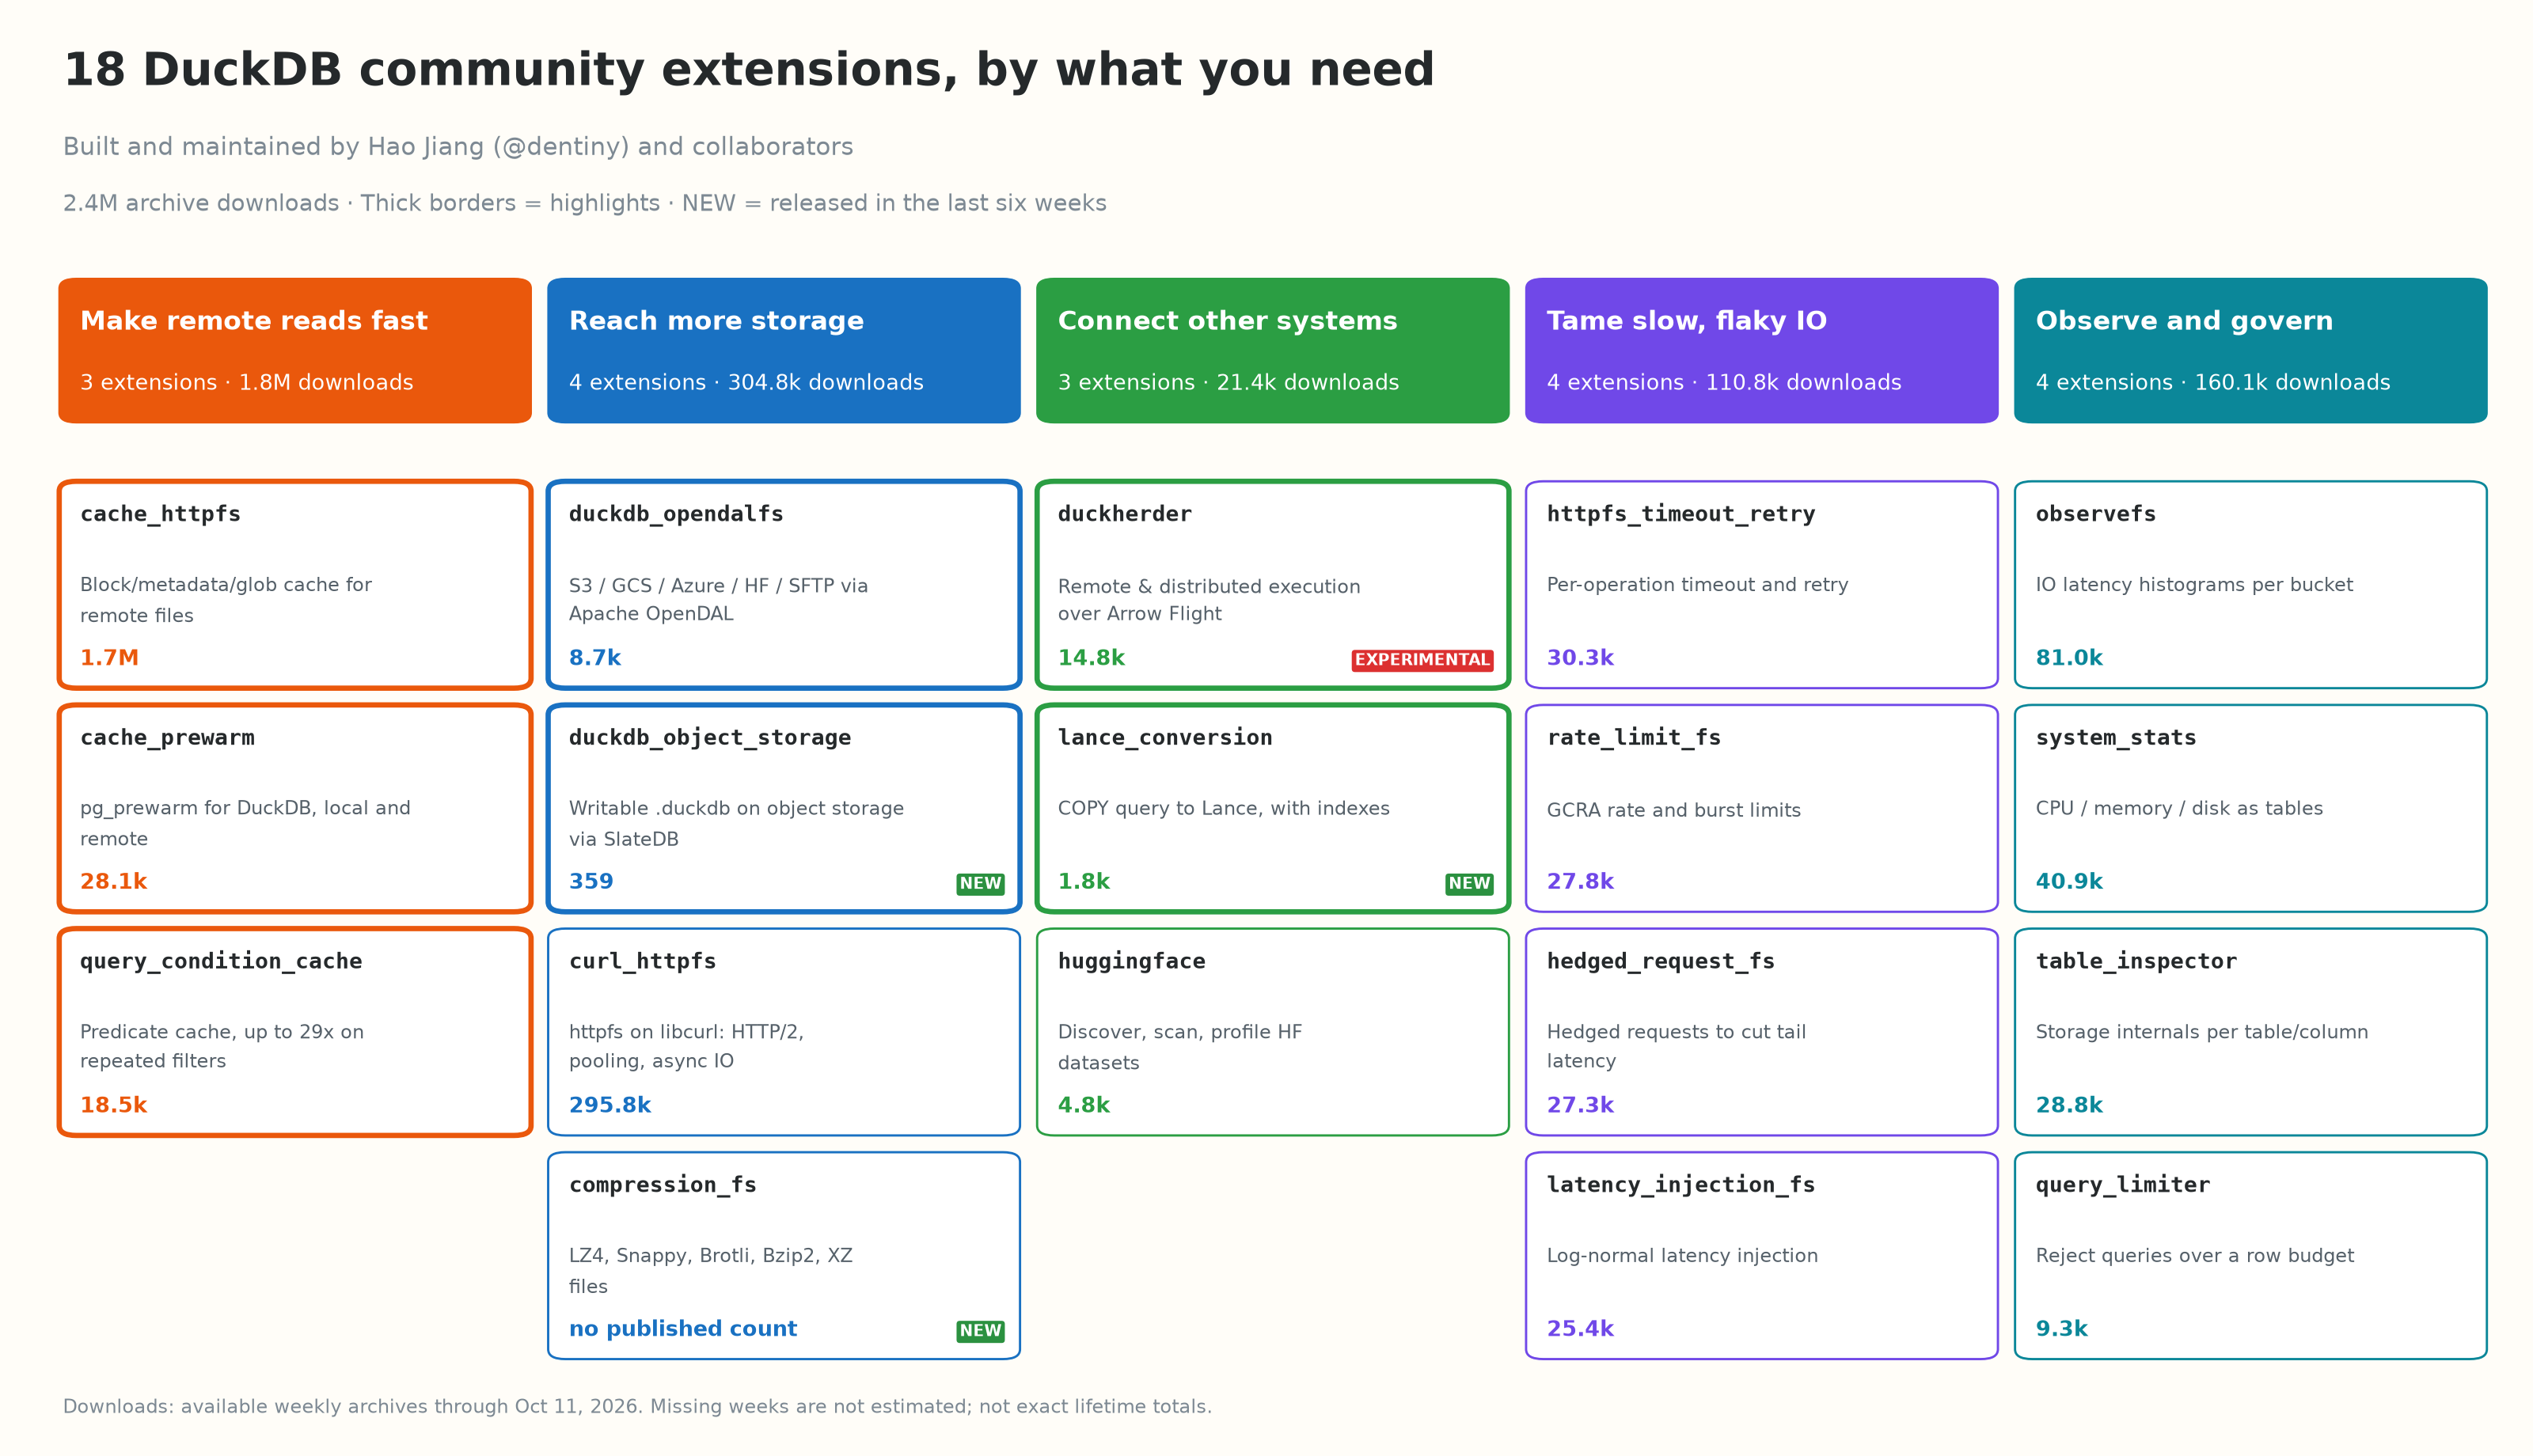
That’s the pattern behind everything in this post. Since March 2025, my collaborators and I have shipped 18 DuckDB extensions, with more than 2.3 million downloads recorded in the available weekly archives. Here’s the short version.
TL;DR
- Small extensions that compose. Each one fixes a single problem, so you load only what you need.
- Seven highlights:
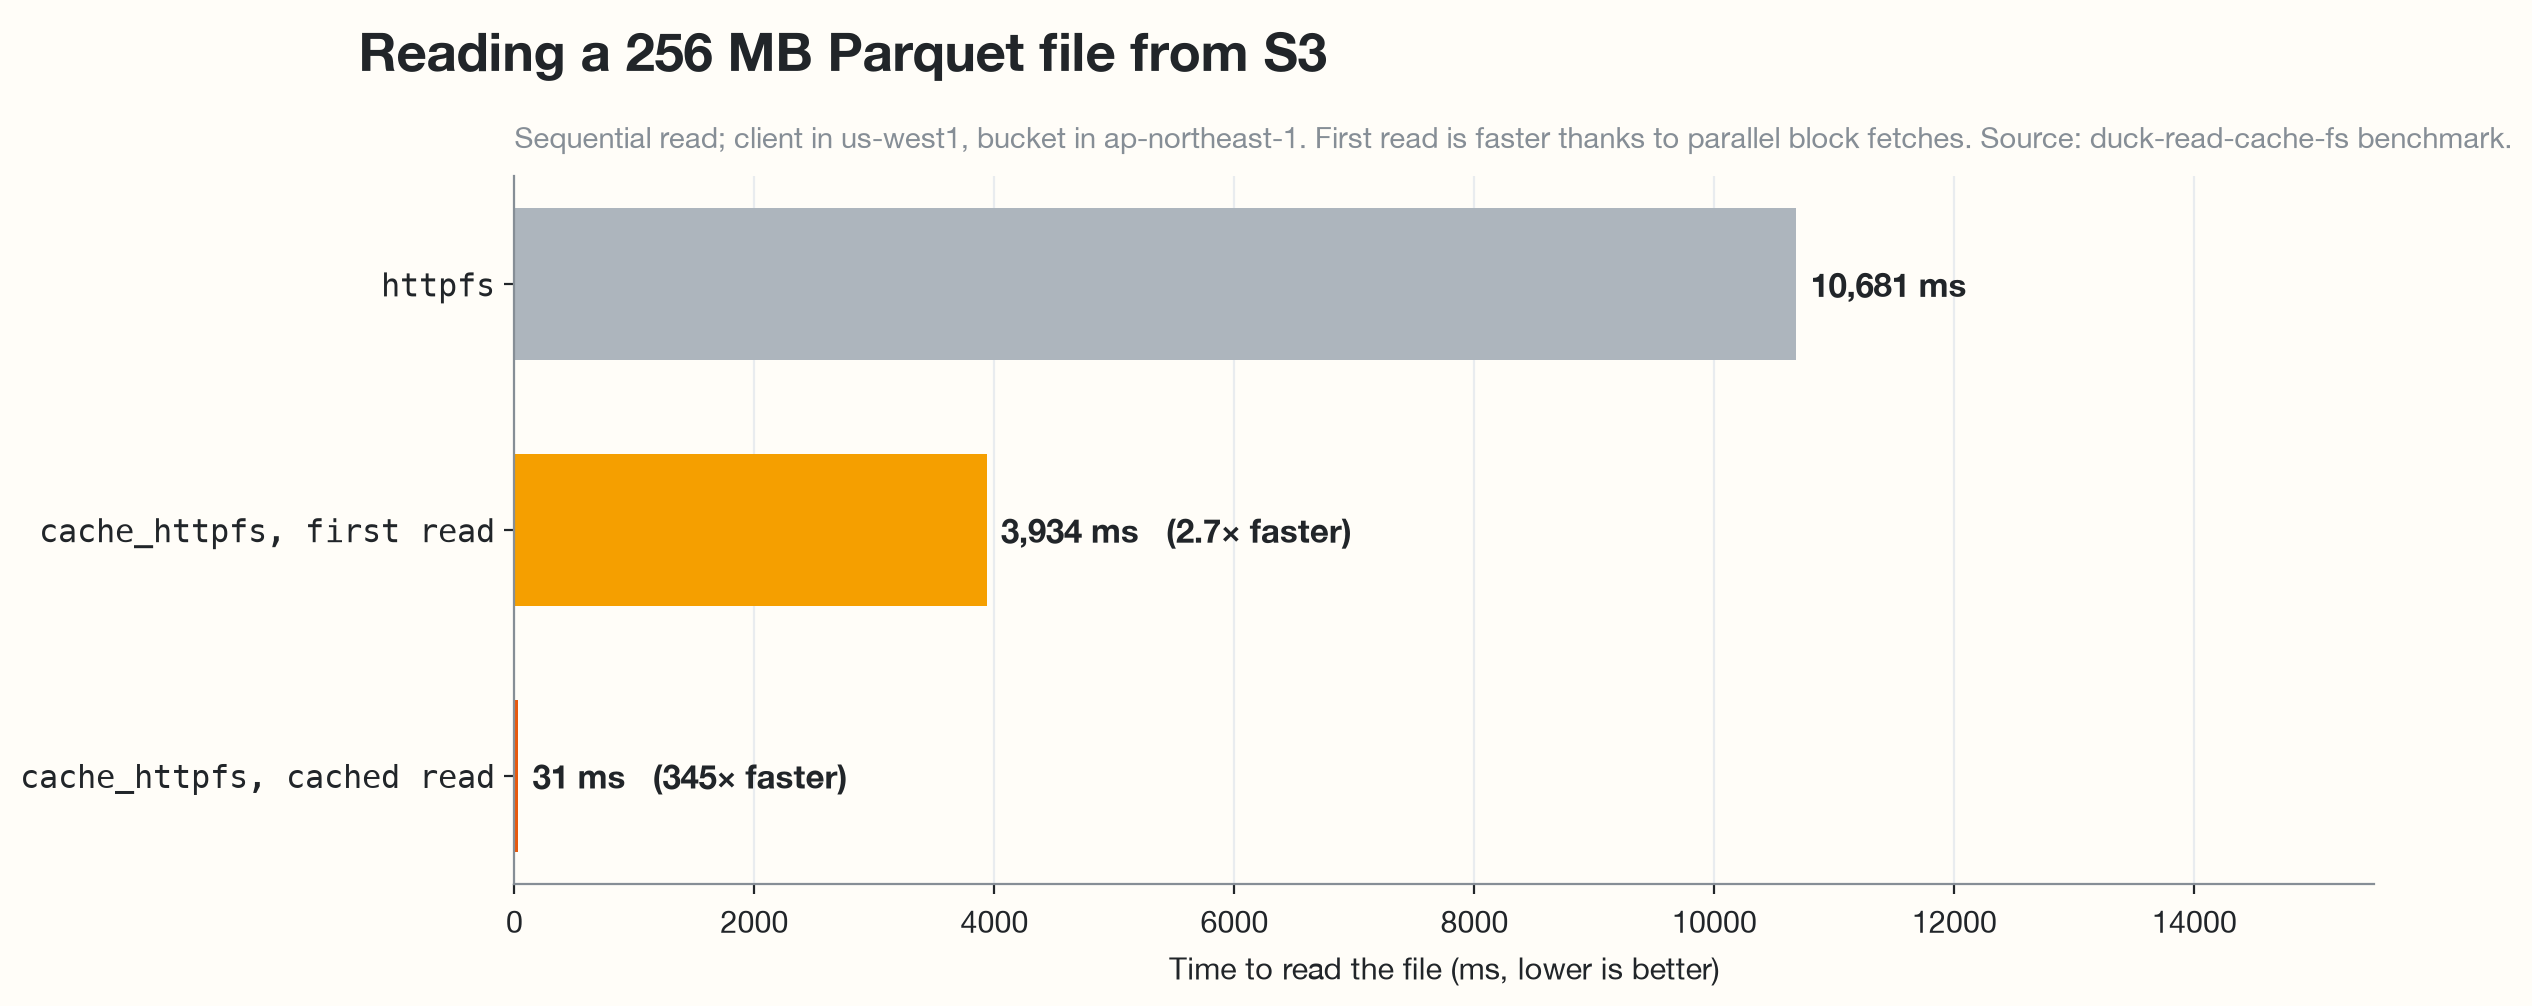
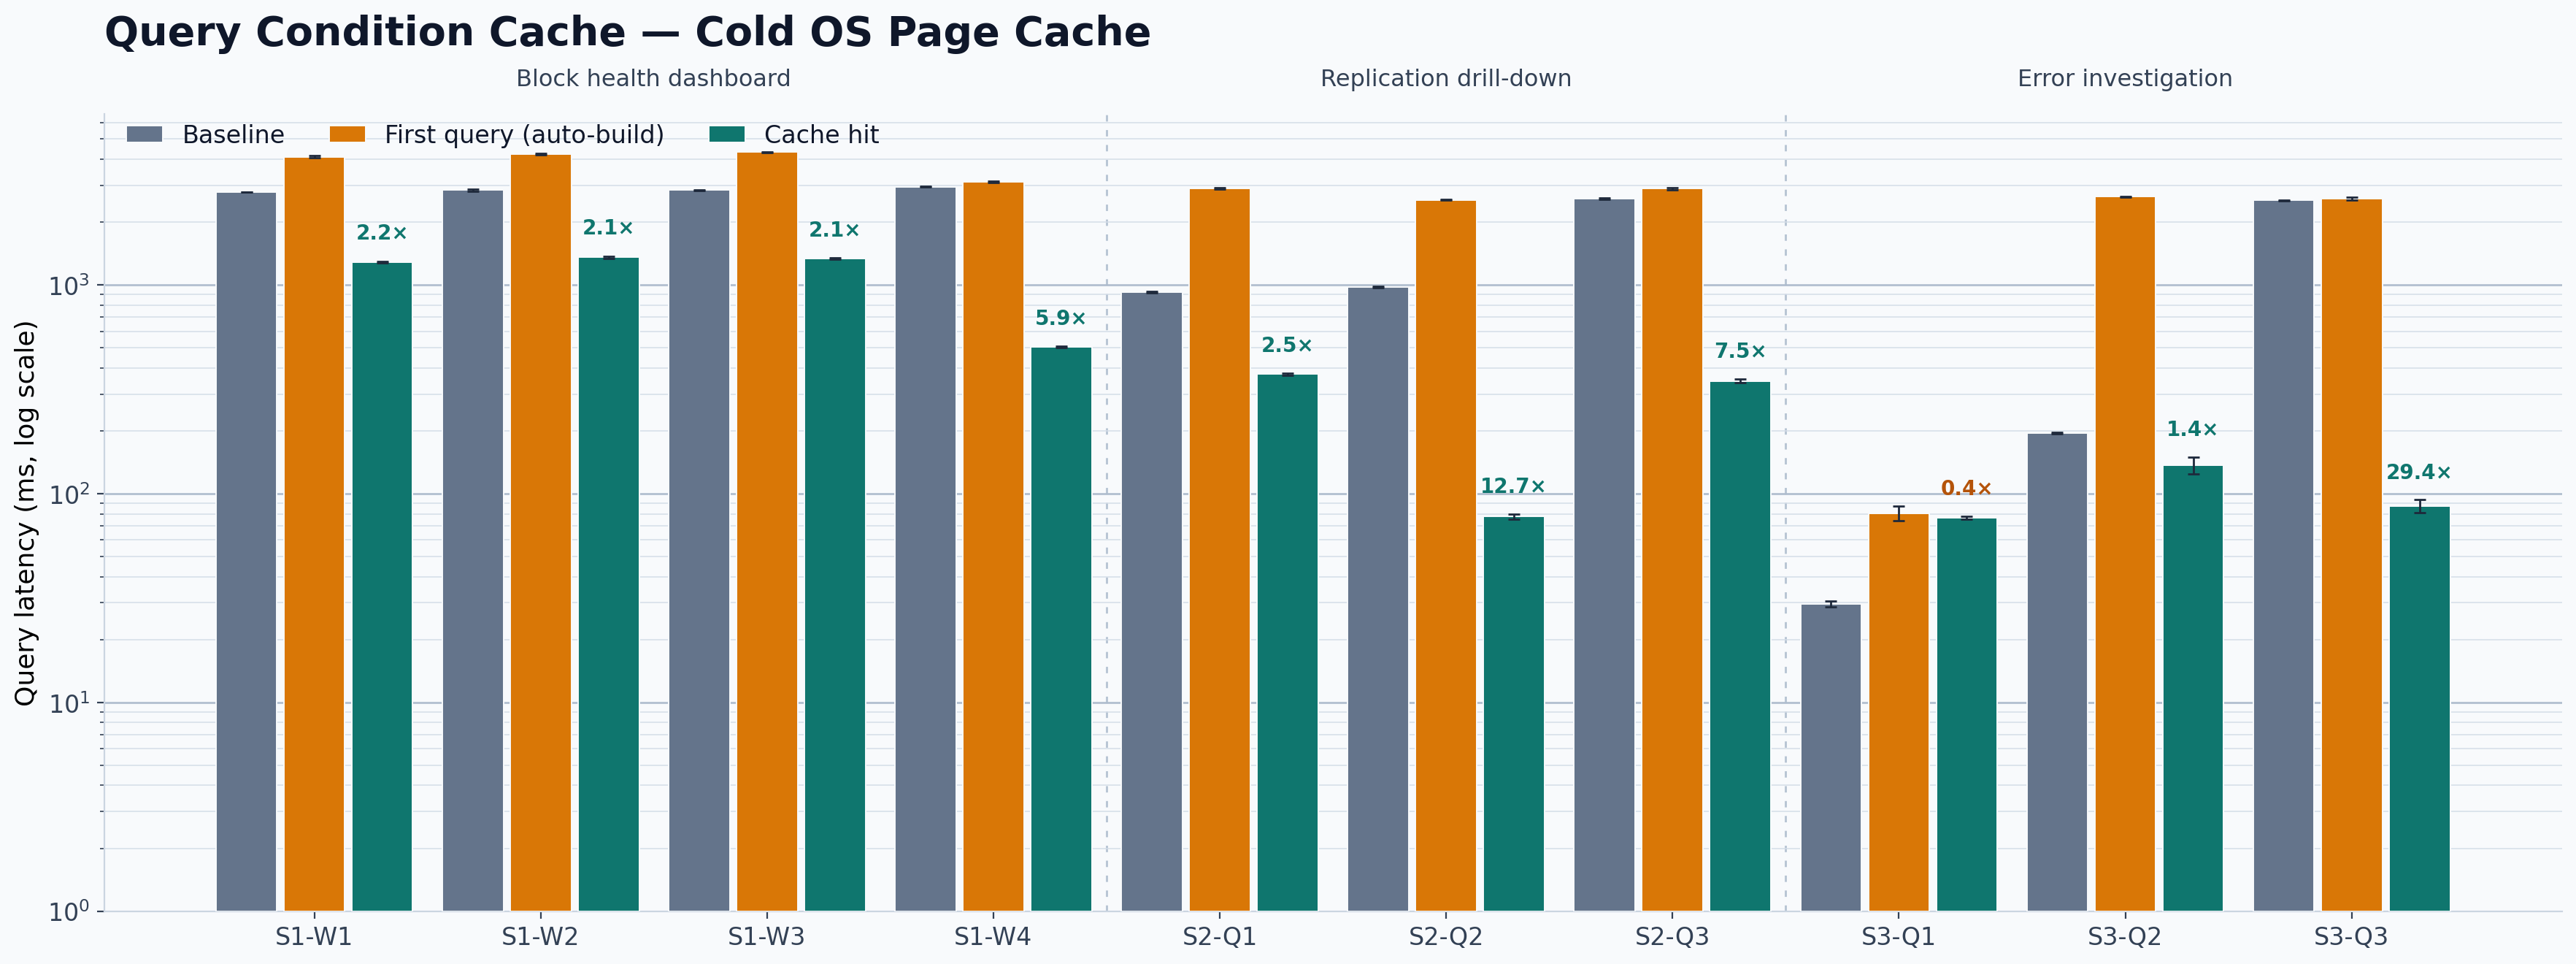
cache_httpfs: a persistent cache that reads S3 data up to 345× fasterquery_condition_cache: a predicate cache that runs repeated queries up to 29× fastercache_prewarm: warms data before the first querylance_conversion: turns any query into an indexed Lance dataset in one statementduckherder: runs your SQL on remote serversduckdb_object_storage: a writable DuckDB database on S3, with any number of read-only readersduckdb_opendalfs: one extension for many storage backends
- I’m looking for feature requests and collaborations. See open problems, or email me at dentinyhao@gmail.com.
What a DuckDB extension is
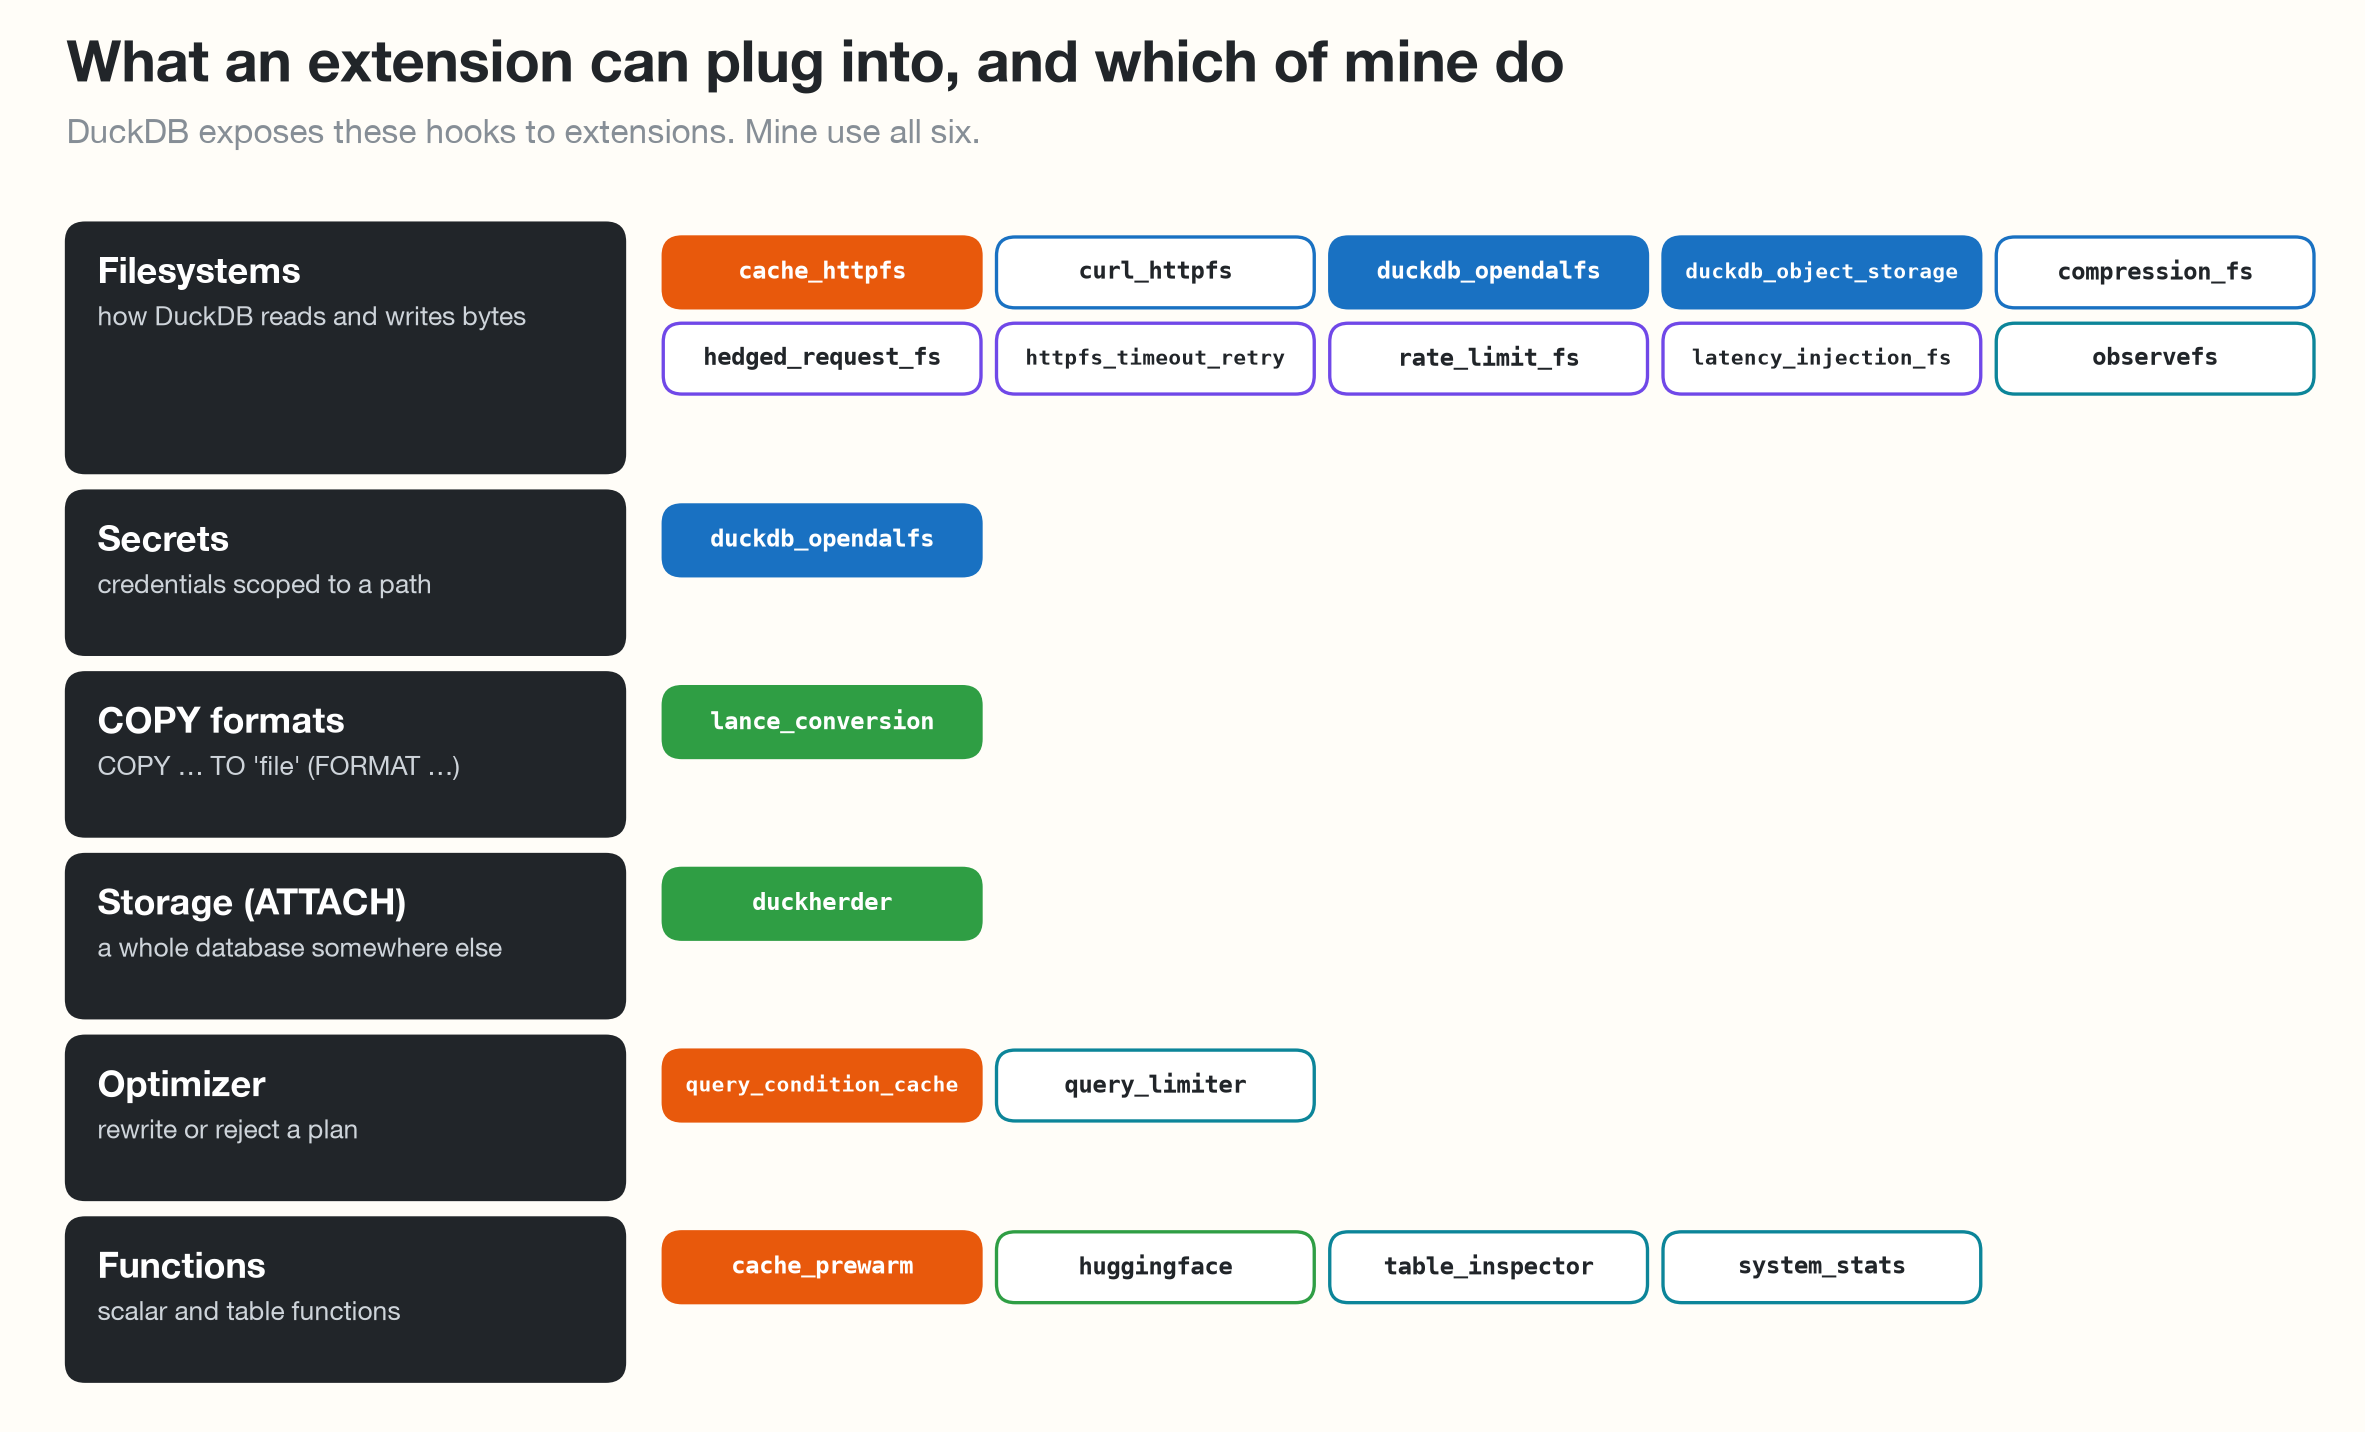
An extension is native code that DuckDB loads into its own process with INSTALL and LOAD. Once loaded, it runs as part of the engine: no separate service, no network hop, no fork of DuckDB. And extensions can do far more than add functions. DuckDB lets them plug in at several levels, from how bytes are read to how a query is planned.
Community extensions are built, signed and distributed by DuckDB for every platform, from a short descriptor in duckdb/community-extensions. Anyone can install one with INSTALL cache_httpfs FROM community;, with no custom repository and no unsigned flag.
How I build them
One extension, one capability. Caching, timeouts, rate limits and hedged requests are four extensions, not four settings in one big one. You can adopt, debug and remove each one on its own.
Minimal setup, works out of the box. INSTALL and LOAD, plus at most a few settings or function calls, should be all you need. Defaults are chosen for the common case: LOAD cache_httpfs alone caches every S3 read on local disk. Tuning knobs exist, but you only touch them when you want to.
Everything composes. Each filesystem extension wraps any registered DuckDB filesystem, including ones I didn’t write, so they stack. Here is a GCS bucket cached on local disk:
LOAD duckdb_opendalfs;   -- reach GCS, Azure, Hugging Face, SFTP, ...
LOAD cache_httpfs;       -- cache blocks, metadata and globs on local disk
CALL cache_httpfs_wrap_cache_filesystem('duckdb_opendalfs');
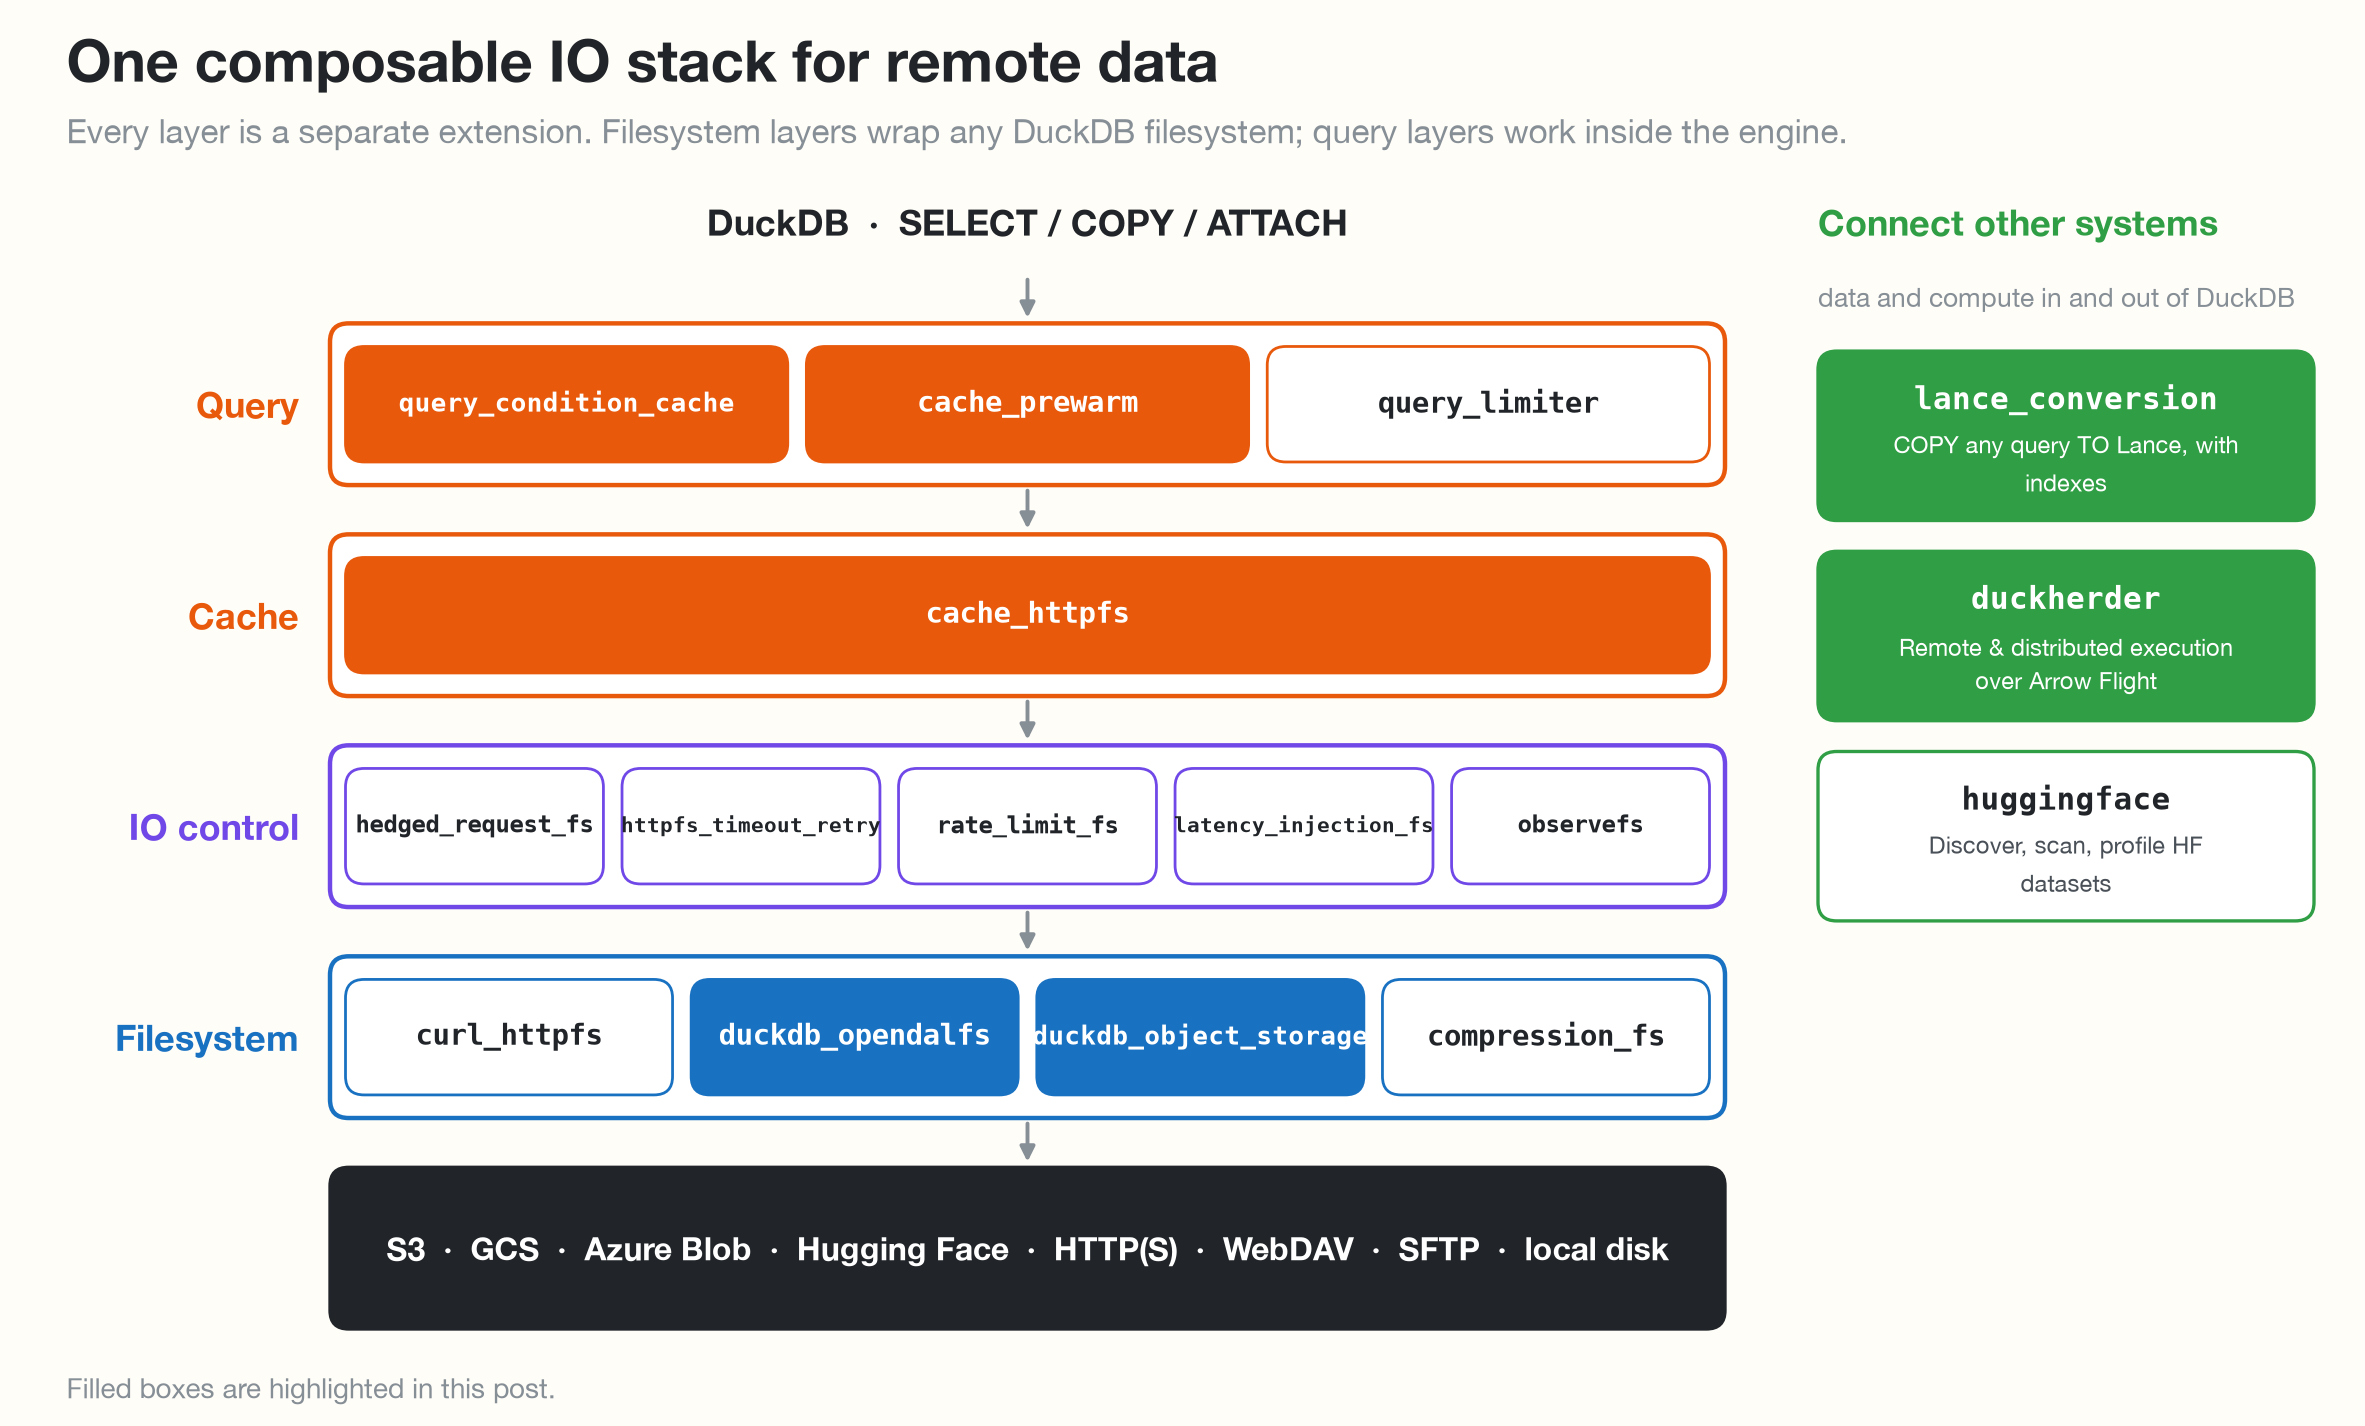
Stay focused. Almost everything I build is about storage, caching, or getting data in and out of DuckDB. The resilience and observability extensions exist to make those three dependable in production.
Why I build them
Two kinds of problems get my attention.
Pain points users already feel, like the disk cache request above:
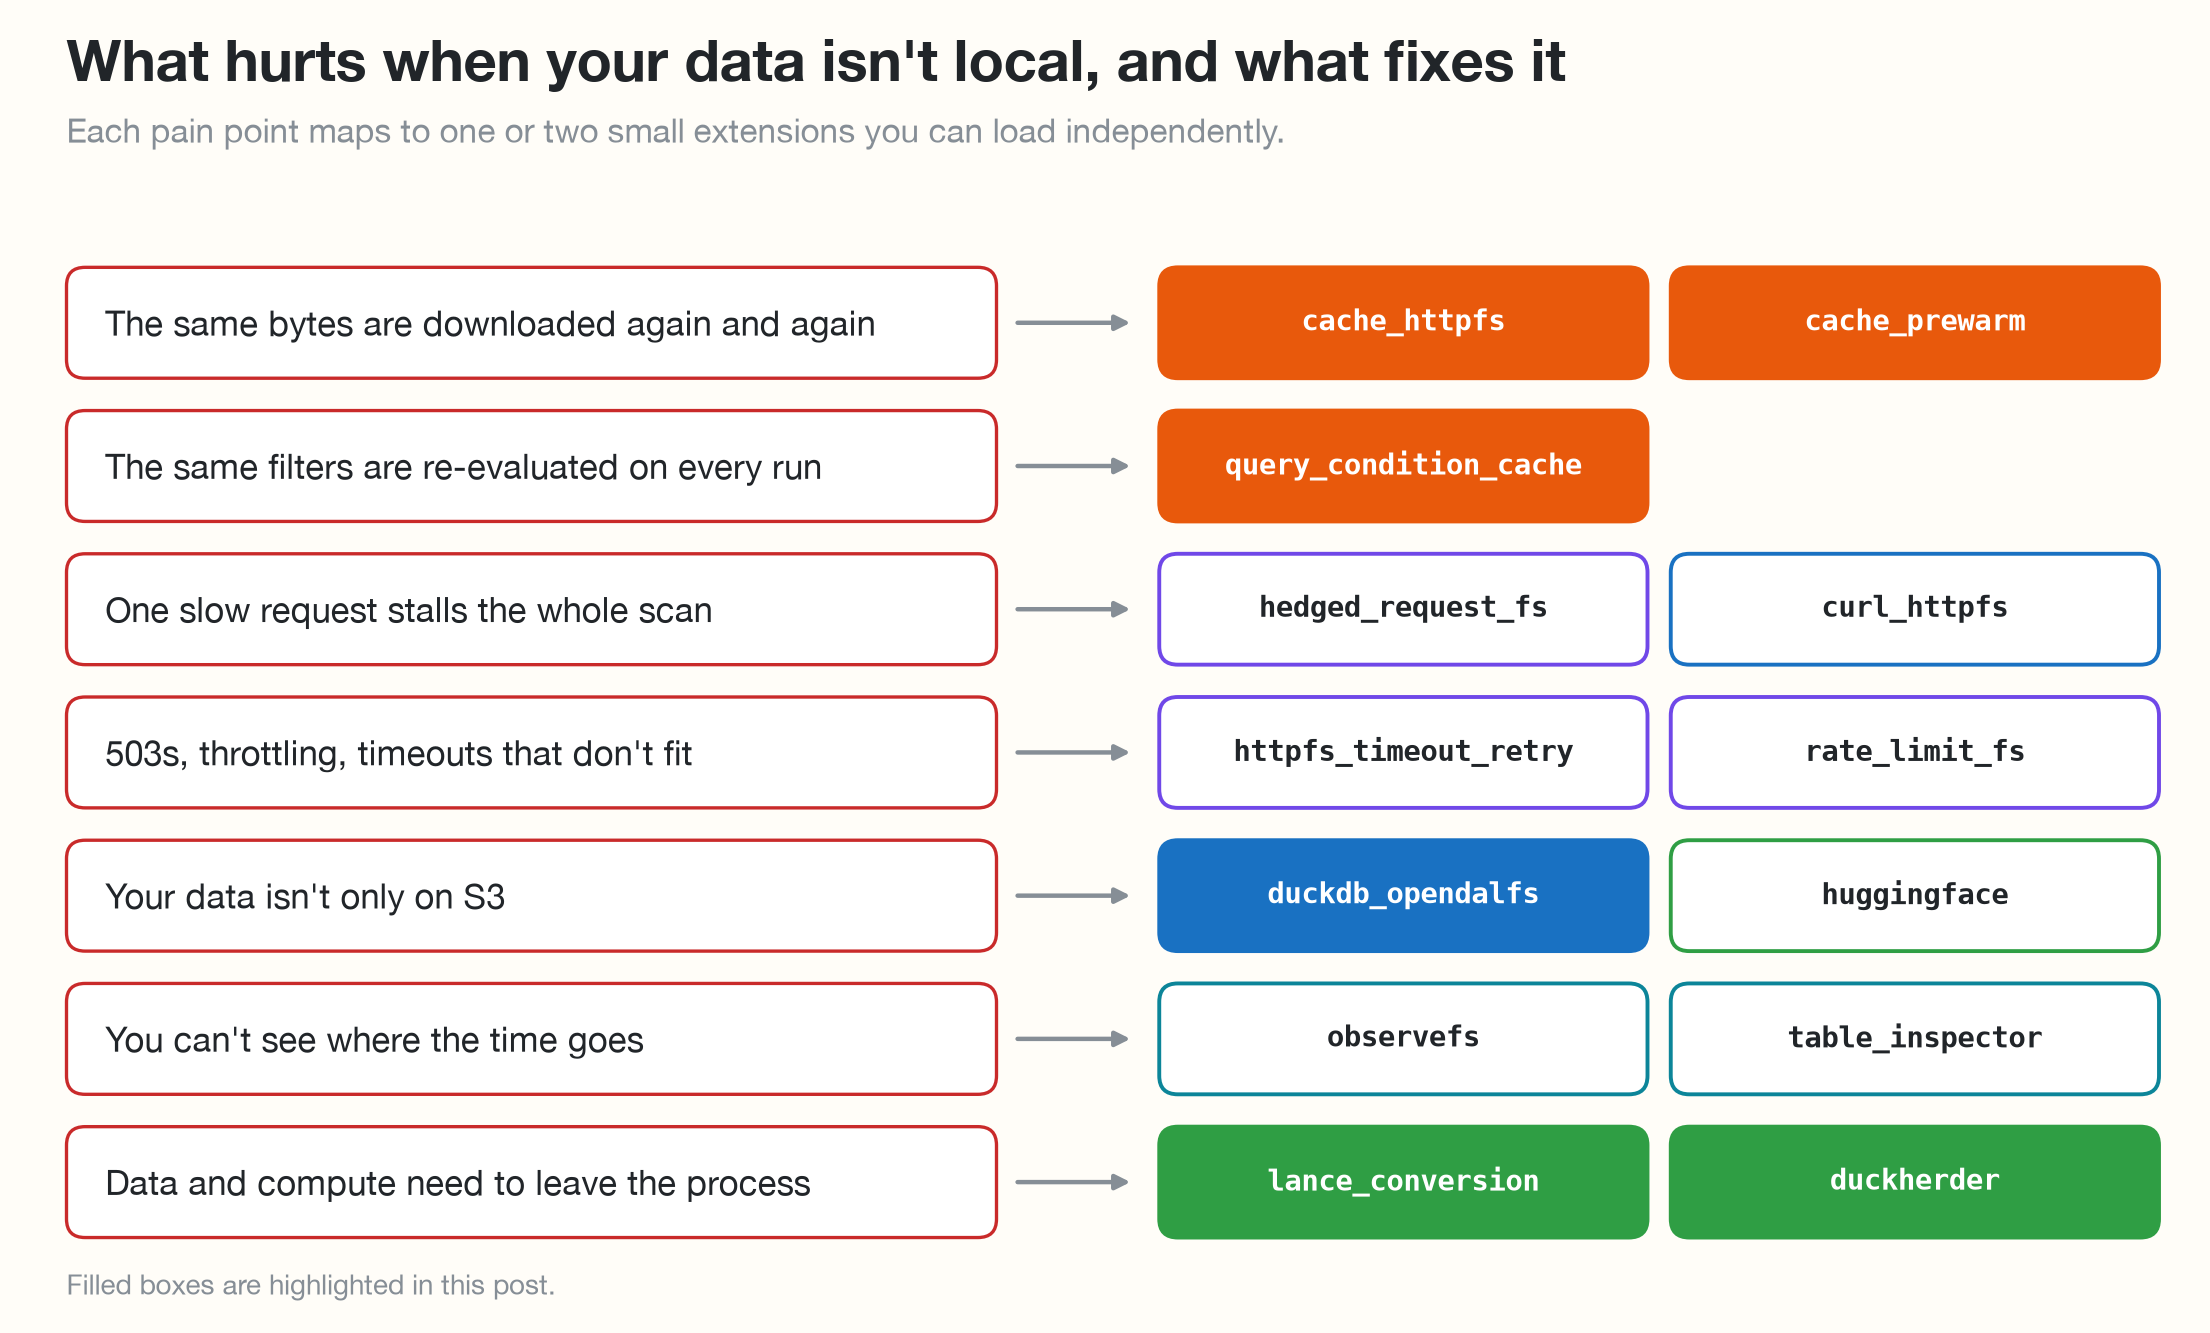
Extending DuckDB’s reach to other systems. These rely on libraries that don’t belong in DuckDB’s core, so they live as extensions:
duckdb_opendalfs: GCS, Azure Blob, Hugging Face, WebDAV, SFTP and more, through Apache OpenDALcompression_fs: LZ4, Snappy, Brotli, Bzip2 and XZ fileslance_conversion: Lance datasetsduckdb_object_storage: databases stored in SlateDBhuggingface: datasets on the Hugging Face Hubduckherder: other DuckDB servers, over Arrow Flight
Highlights
Each highlight follows the same pattern: what it fixes, a picture, the SQL to try it, and where it fits.
cache_httpfs: a persistent read cache for remote files
DuckDB’s built-in file cache lives in memory and disappears when the process exits. cache_httpfs is a drop-in replacement for httpfs that keeps data blocks, metadata, file handles and glob results on local disk, and fetches large reads in parallel. With more than 1.7 million downloads recorded in the available weekly archives, it has been in the community top 10 every archived week since March 2026.
INSTALL cache_httpfs FROM community;
LOAD cache_httpfs;   -- loads httpfs for you; on-disk cache is the default

SELECT count(*) FROM 's3://my-bucket/events/*.parquet';   -- cold: fetched from S3
SELECT count(*) FROM 's3://my-bucket/events/*.parquet';   -- warm: read from local disk
Best for dashboards, notebooks and CI jobs that read the same remote files again and again. Not for tiny random reads, which pay for block alignment; lower cache_httpfs_cache_block_size if that’s your workload.
query_condition_cache: a predicate cache
Dashboards and log investigations run the same WHERE clauses all day. Zone maps rarely help with LIKE patterns or unsorted columns, so DuckDB scans again on every run. This extension remembers which vectors matched a predicate and skips the rest next time, following the SIGMOD ‘24 paper Predicate Caching and ClickHouse’s query condition cache. On HDFS logs (58 million records), cache hits were up to 29× faster with a cold OS page cache and up to 14× with warm storage; Andrew’s write-up has the design and full results.
INSTALL query_condition_cache FROM community;
LOAD query_condition_cache;

-- Built on the first run, used on later runs.
SELECT count(*) FROM logs WHERE level = 'ERROR' AND msg LIKE '%timeout%';
Best for selective filters that repeat over native DuckDB tables. Not for one-off queries, since the first run pays for an extra scan to build the entry, or broad filters with little to skip. Parquet scans are on the roadmap.
cache_prewarm: pg_prewarm for DuckDB
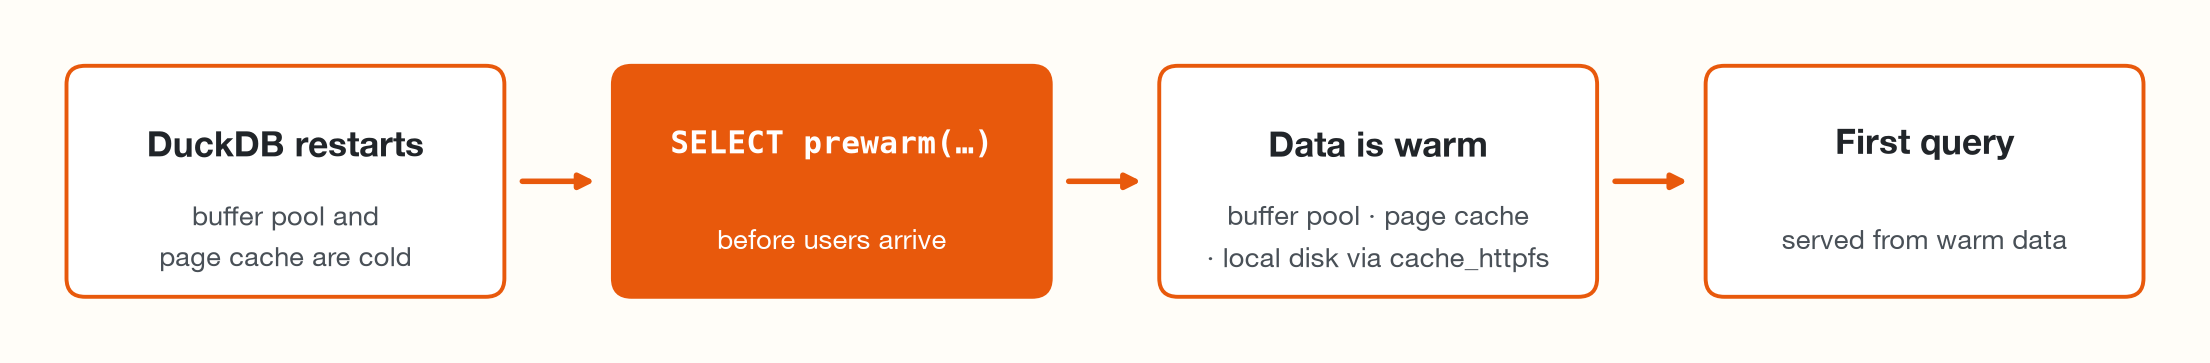
The first query after a restart shouldn’t be the slow one. Modeled on PostgreSQL’s pg_prewarm, this loads data before users arrive: into DuckDB’s buffer pool, into the OS page cache, or, with cache_httpfs, from S3 to local disk.
INSTALL cache_prewarm FROM community;
LOAD cache_prewarm;

SELECT prewarm('events');                              -- buffer pool
SELECT prewarm('events', 'read', '4GB');               -- OS page cache, capped at 4 GB
SELECT prewarm_remote('s3://lake/events/*.parquet');   -- remote files, via cache_httpfs
Best for long-running services and dashboards that restart and need a fast first query. Not for data much larger than memory: prewarming stops at 80% of the free buffer pool, so raise memory_limit or prewarm only the hot tables.
lance_conversion: COPY any query to Lance
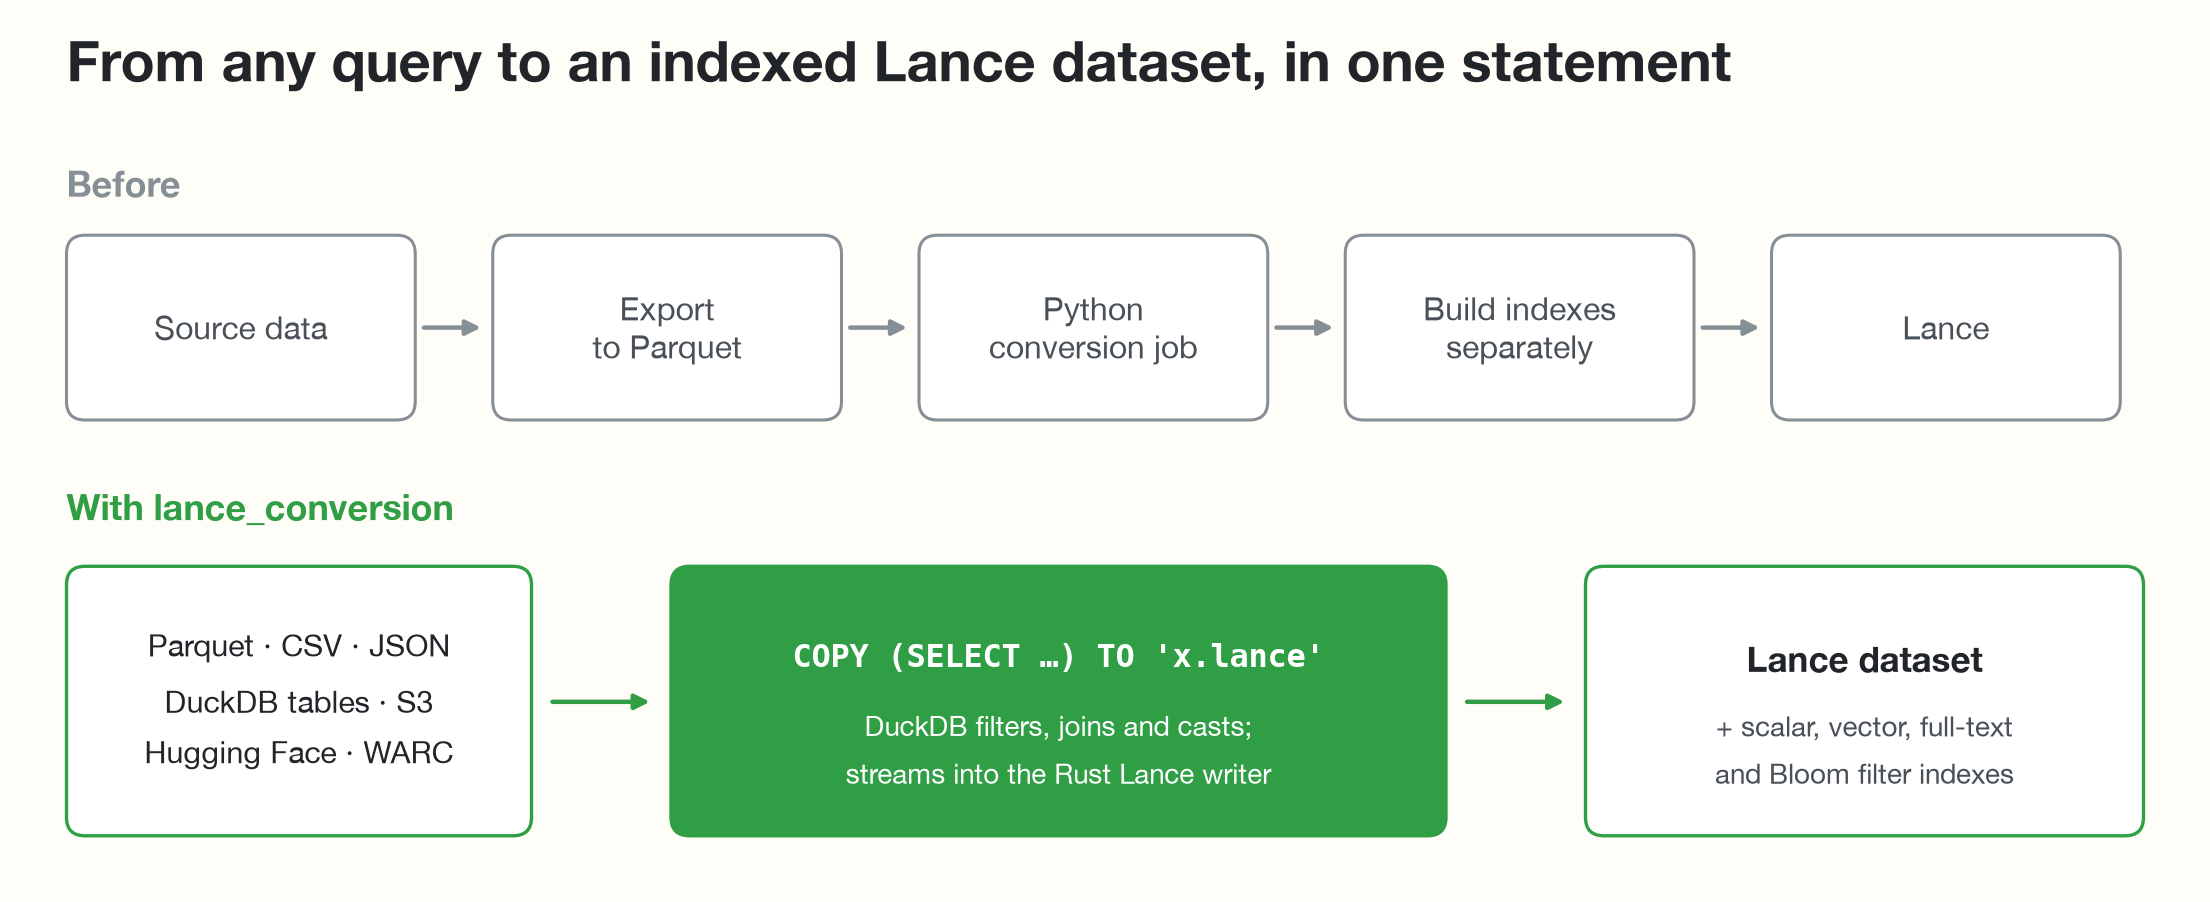
Getting data into Lance usually means exporting files and running a separate conversion job. This extension makes it one COPY statement, with indexes built along the way. Released in September 2026, it recorded 684 downloads in the latest published rolling week.
INSTALL lance_conversion FROM community;
LOAD lance_conversion;

COPY (
  SELECT id, category, description, embedding, asset_uri
  FROM read_parquet('s3://lake/catalog/**/*.parquet')
) TO 's3://lake/catalog.lance' (
  FORMAT LANCE,
  PRESERVE_ORDER false,                  -- one writer per DuckDB thread
  BLOB_COLUMNS (asset_uri),
  SCALAR_INDEX_COLUMNS (id, category),
  VECTOR_INDEX_COLUMNS (embedding),
  TEXT_INDEX_COLUMNS (description)
);
Best for turning Parquet, JSON, Hugging Face datasets or WARC archives into indexed Lance datasets for search and ML. It also supports append, overwrite and random sampling. Not for Windows x64, Intel Macs or the browser yet; those builds are excluded.
duckherder: remote and distributed execution
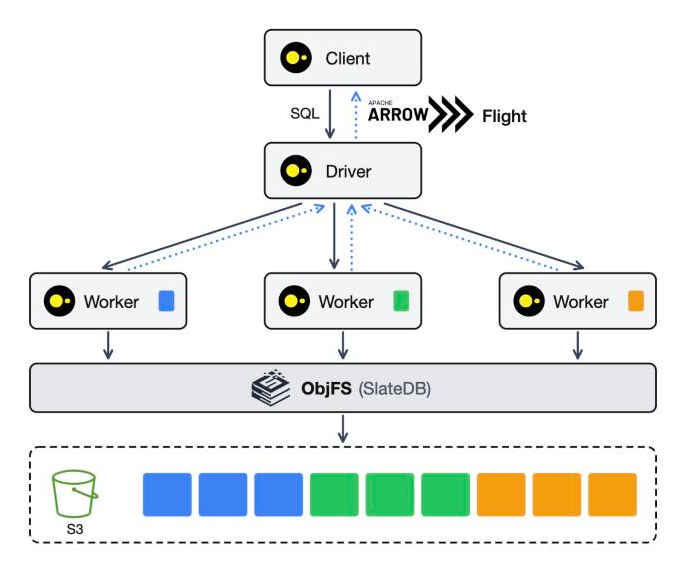
Attach a remote DuckDB server like a local database and keep writing the same SQL. A driver plans and partitions each query, workers execute the pieces, and results come back over Arrow Flight. In the target design, the driver owns a single writer on duckdb_object_storage and every worker reads from S3.
INSTALL duckherder FROM community;
LOAD duckherder;
SELECT duckherder_start_local_server(8815);
ATTACH DATABASE 'localhost:8815' AS dh (TYPE duckherder);

CREATE TABLE dh.events (id INTEGER, category VARCHAR);
INSERT INTO dh.events VALUES (1, 'click'), (2, 'view'), (3, 'click');
SELECT category, count(*) FROM dh.events GROUP BY ALL;
Best for experimenting with remote and distributed DuckDB without changing your SQL. Not for production yet: it’s experimental, joins still run on the driver, and authentication and worker failover are open problems. It’s a personal project, not affiliated with DuckDB Labs, and the most ambitious item on this list.
duckdb_object_storage: a writable DuckDB database on object storage
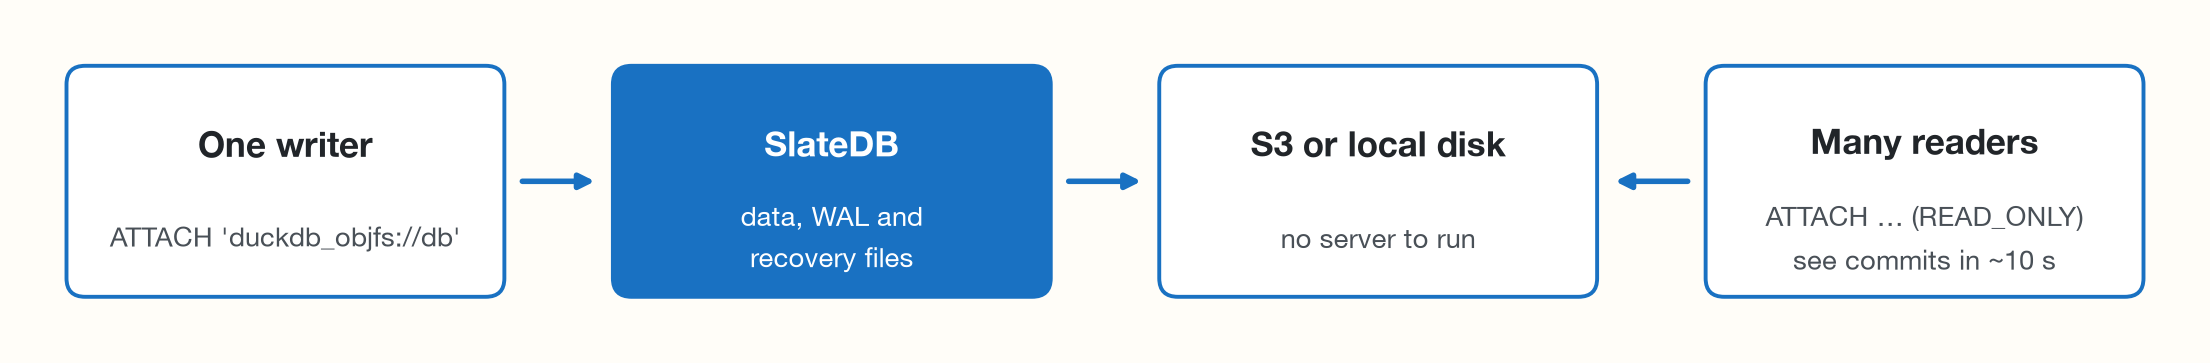
DuckDB can attach a .duckdb file on S3 read-only, but writing one has needed a local disk. This extension keeps the whole database in SlateDB, including the write-ahead log and recovery files, on S3-compatible storage or local disk, behind a duckdb_objfs:// path. SlateDB’s in-memory cache is on by default, a local disk cache is one setting away, and duckdb_objfs_cache_stats() and duckdb_objfs_io_stats() show what’s happening.
INSTALL duckdb_object_storage FROM community;
LOAD cache_httpfs;   -- registers the S3 secret type
LOAD duckdb_object_storage;

CREATE SECRET (TYPE S3, KEY_ID '...', SECRET '...', REGION 'us-east-1', SCOPE 's3://my-bucket/duckdb-data');
SET duckdb_objfs_backend = 's3';
SET duckdb_objfs_bucket = 'my-bucket';
SET duckdb_objfs_root = 'duckdb-data';

ATTACH 'duckdb_objfs://analytics.db' AS analytics;
CREATE TABLE analytics.items (i INTEGER);
INSERT INTO analytics.items VALUES (1), (2);
Best for one writer and any number of READ_ONLY readers sharing a database on S3, with no server to run. Not for multiple writers: there’s no file locking yet, so a second writer takes over and the first only finds out when its next flush fails. Run a single writer.
duckdb_opendalfs: one extension, many backends
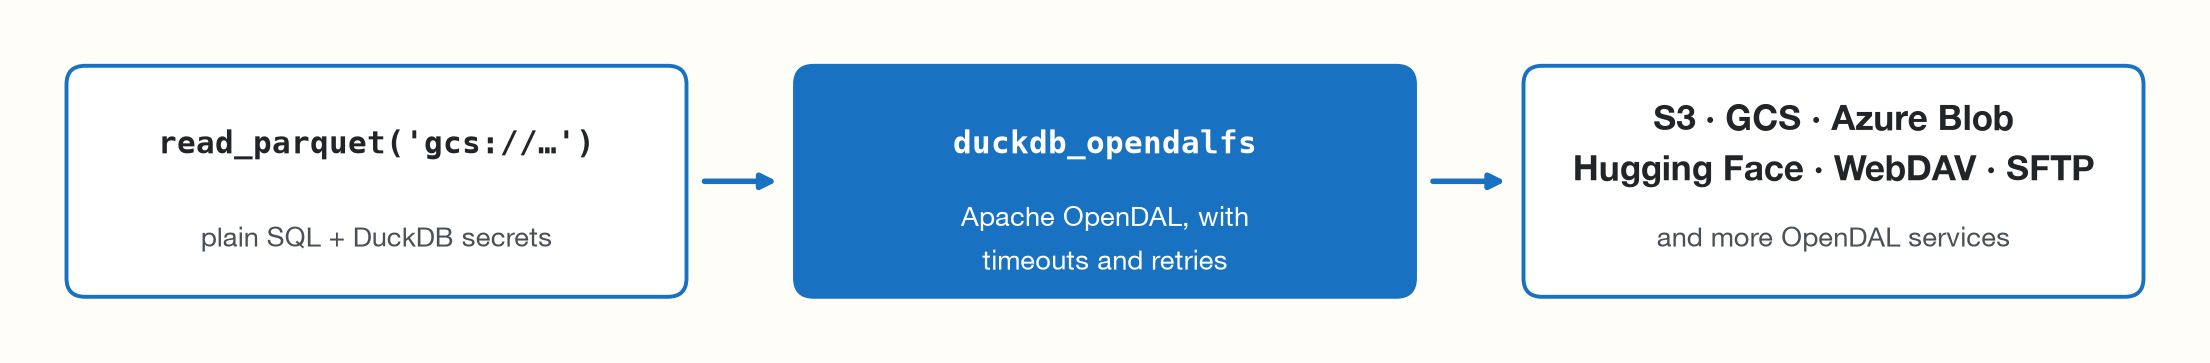
Built on Apache OpenDAL, it covers S3-compatible stores, GCS, Azure Blob, Hugging Face, WebDAV, SFTP and more through ordinary DuckDB secrets, with timeouts and retries on by default.
INSTALL duckdb_opendalfs FROM community;
LOAD duckdb_opendalfs;

CREATE SECRET prod_gcs (TYPE opendal_gcs, SCOPE 'gcs://analytics', TOKEN '...');
SELECT * FROM read_parquet('gcs://analytics/events.parquet');
Best for storage that DuckDB’s built-in filesystems don’t reach, and one secrets model across all of them. Pair it with cache_httpfs to cache any backend on local disk. Not for squeezing the last bit of read throughput yet: every read currently pays an extra memory copy (DuckDB discussion #21546).
The other eleven extensions each get a one-line summary on the map at the top of this post.
All 18 repositories
| Extension | Repository |
|---|---|
cache_httpfs |
dentiny/duck-read-cache-fs |
query_condition_cache |
dentiny/duckdb-query-condition-cache |
cache_prewarm |
dentiny/duckdb-cache-prewarm |
lance_conversion |
dentiny/duckdb_lance_conversion |
duckherder |
dentiny/duckdb-distributed-execution |
duckdb_opendalfs |
dentiny/duckdb-opendal-filesystem |
curl_httpfs |
dentiny/duckdb-curl-filesystem |
duckdb_object_storage |
dentiny/duckdb-object-storage |
compression_fs |
dentiny/duckdb-compression-filesystem |
hedged_request_fs |
dentiny/duckdb-hedged-request |
httpfs_timeout_retry |
dentiny/duckdb-httpfs-timeout-retry |
rate_limit_fs |
dentiny/duckdb-rate-limit-filesystem |
latency_injection_fs |
dentiny/duckdb-filesystem-latency-injection |
observefs |
dentiny/duckdb-filesystem-observability |
table_inspector |
dentiny/duckdb-table-inspector |
system_stats |
dentiny/system_stats |
query_limiter |
dentiny/duckdb-query-limiter |
huggingface |
dentiny/duckdb-huggingface |
By the numbers
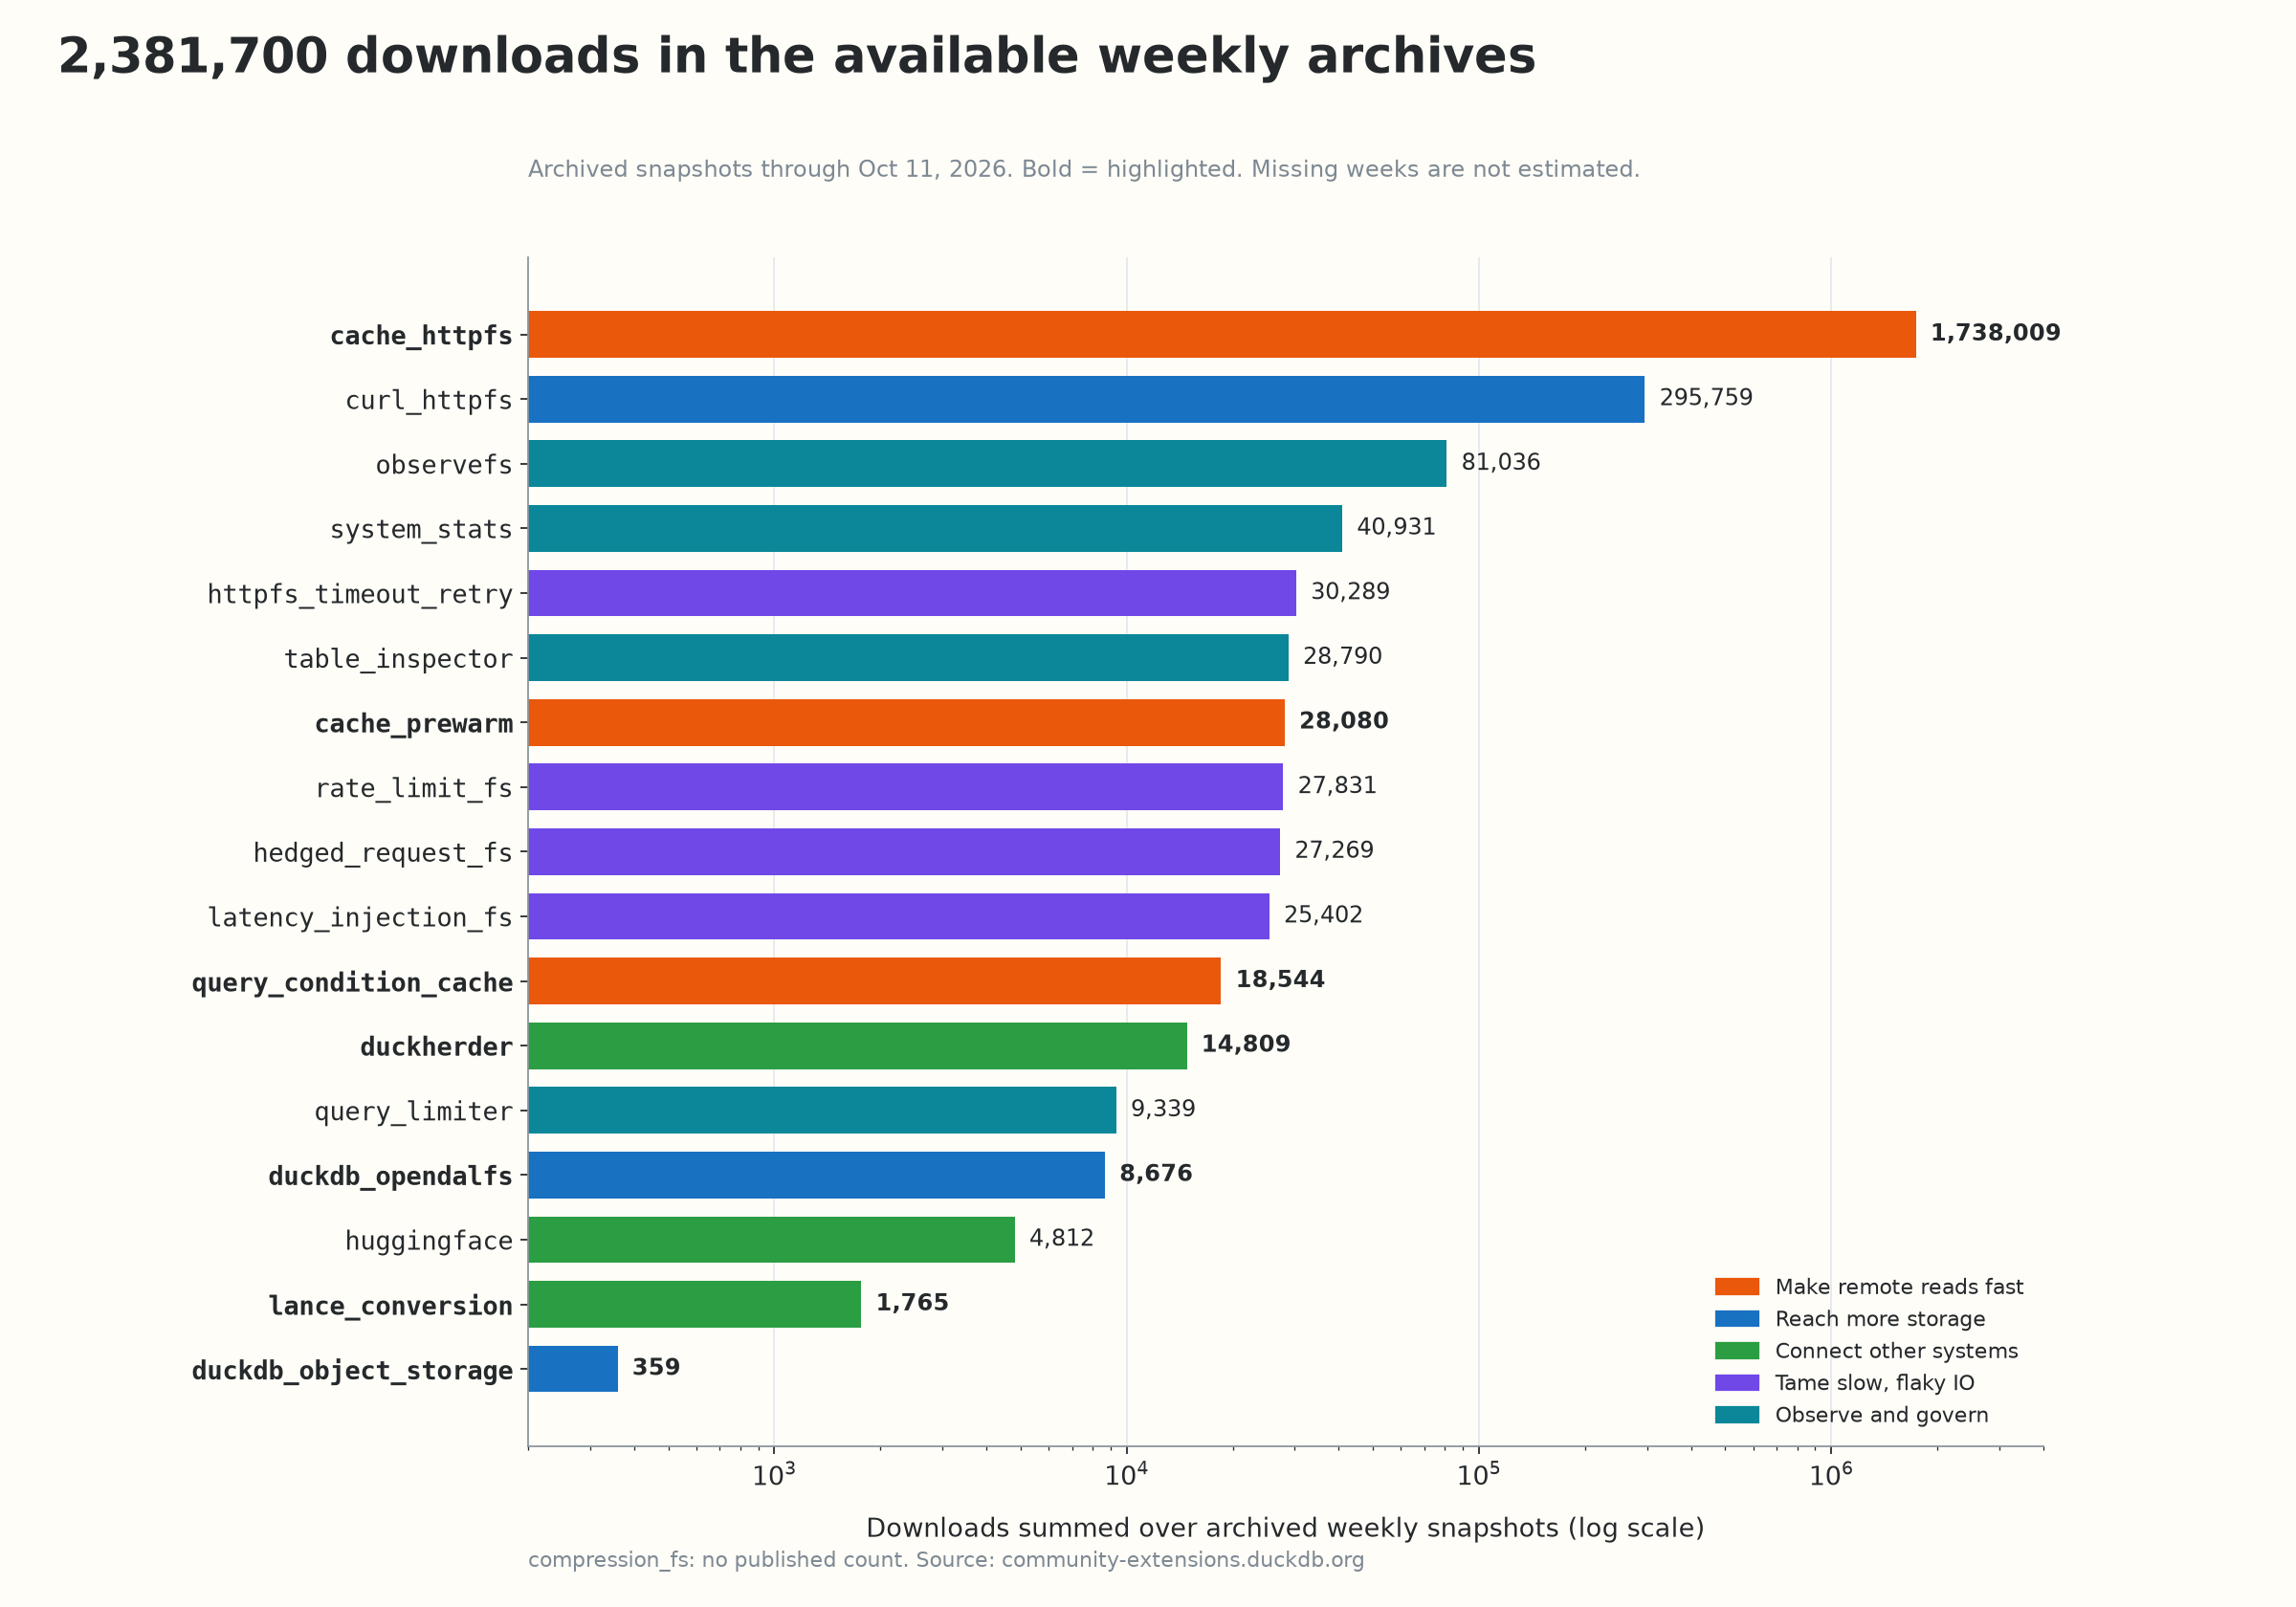
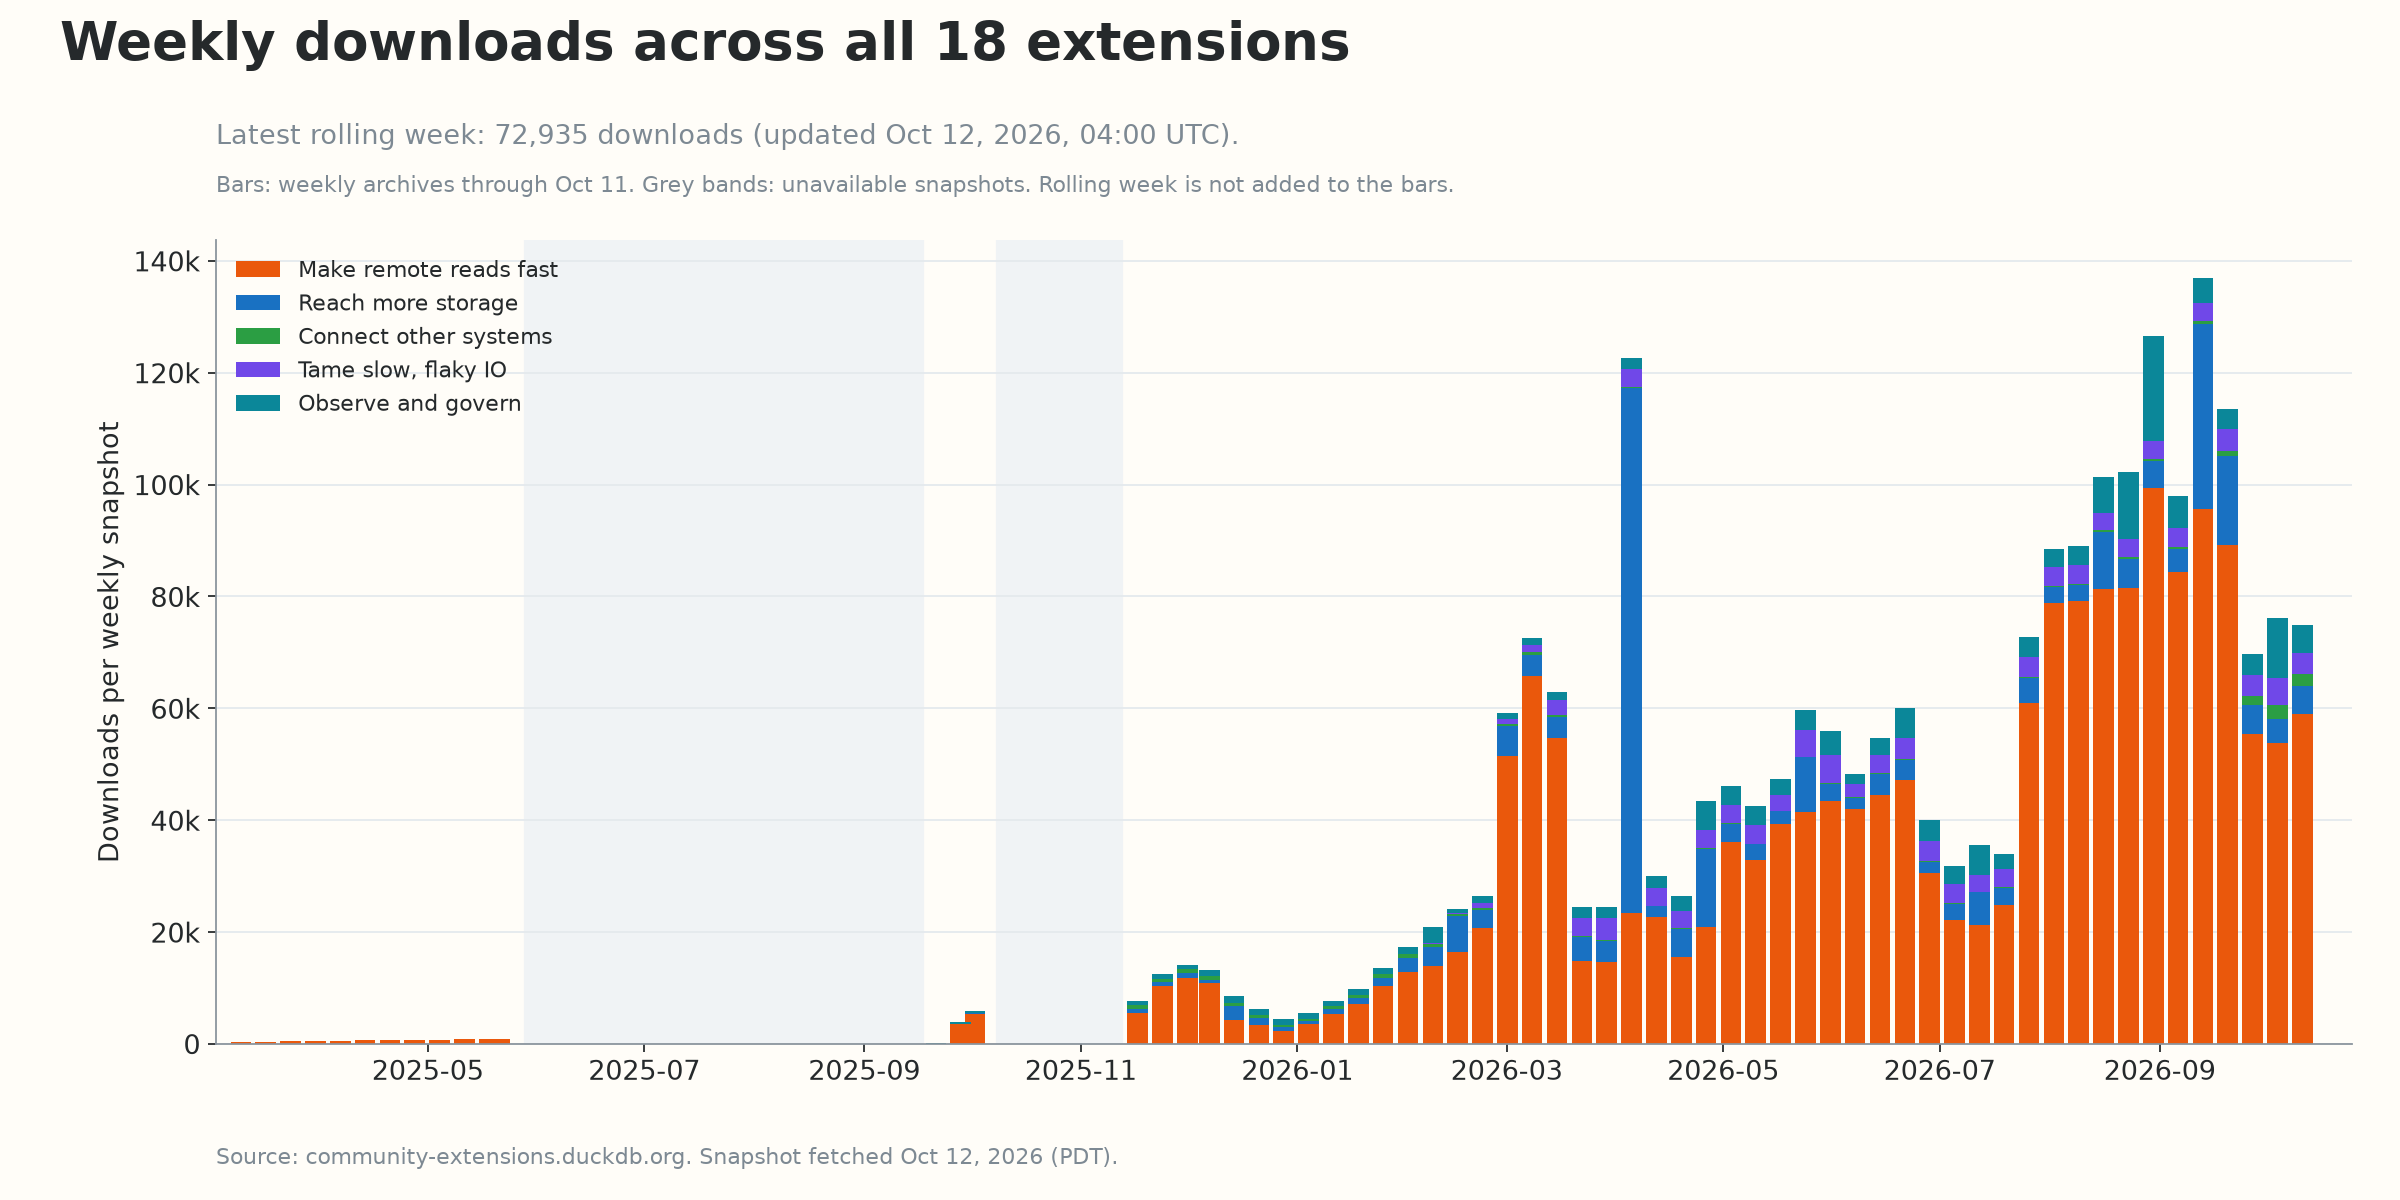
Statistics refreshed October 12, 2026, at 18:43:40 PDT (October 13, 01:43:40 UTC). The latest rolling-week report was updated October 12 at 04:00:07 UTC; these are the latest official figures available at retrieval, rather than a live counter. The 18 extensions have 72,935 reported downloads in that rolling week.
Archive totals sum the available weekly snapshots from 2025 week 10 through 2026 week 41 (latest update: October 11, 2026, 04:00:07 UTC). The current week 42 report overlaps week 41, so it is shown separately and is not added to the archive totals. Missing weeks are not estimated, and some older snapshots were taken at irregular intervals: these sums are not exact lifetime totals. DuckDB’s download metrics estimate downloads across versions and platforms, not unique users. A dash means no published count; totals include only reported values.
Full table
| Extension | Group | First release | Archive downloads |
|---|---|---|---|
cache_httpfs |
Remote reads | 2025-03 | 1,738,009 |
curl_httpfs |
Storage | 2025-09 | 295,759 |
observefs |
Observe | 2025-09 | 81,036 |
system_stats |
Observe | 2025-12 | 40,931 |
httpfs_timeout_retry |
Flaky IO | 2026-02 | 30,289 |
table_inspector |
Observe | 2026-02 | 28,790 |
cache_prewarm |
Remote reads | 2026-02 | 28,080 |
rate_limit_fs |
Flaky IO | 2026-02 | 27,831 |
hedged_request_fs |
Flaky IO | 2026-02 | 27,269 |
latency_injection_fs |
Flaky IO | 2026-03 | 25,402 |
query_condition_cache |
Remote reads | 2026-04 | 18,544 |
duckherder |
Other systems | 2025-11 | 14,809 |
query_limiter |
Observe | 2026-07 | 9,339 |
duckdb_opendalfs |
Storage | 2026-07 | 8,676 |
huggingface |
Other systems | 2026-08 | 4,812 |
lance_conversion |
Other systems | 2026-09 | 1,765 |
duckdb_object_storage |
Storage | 2026-09 | 359 |
compression_fs |
Storage | 2026-09 | — |
| Total reported | 2,381,700 |
Let’s build together
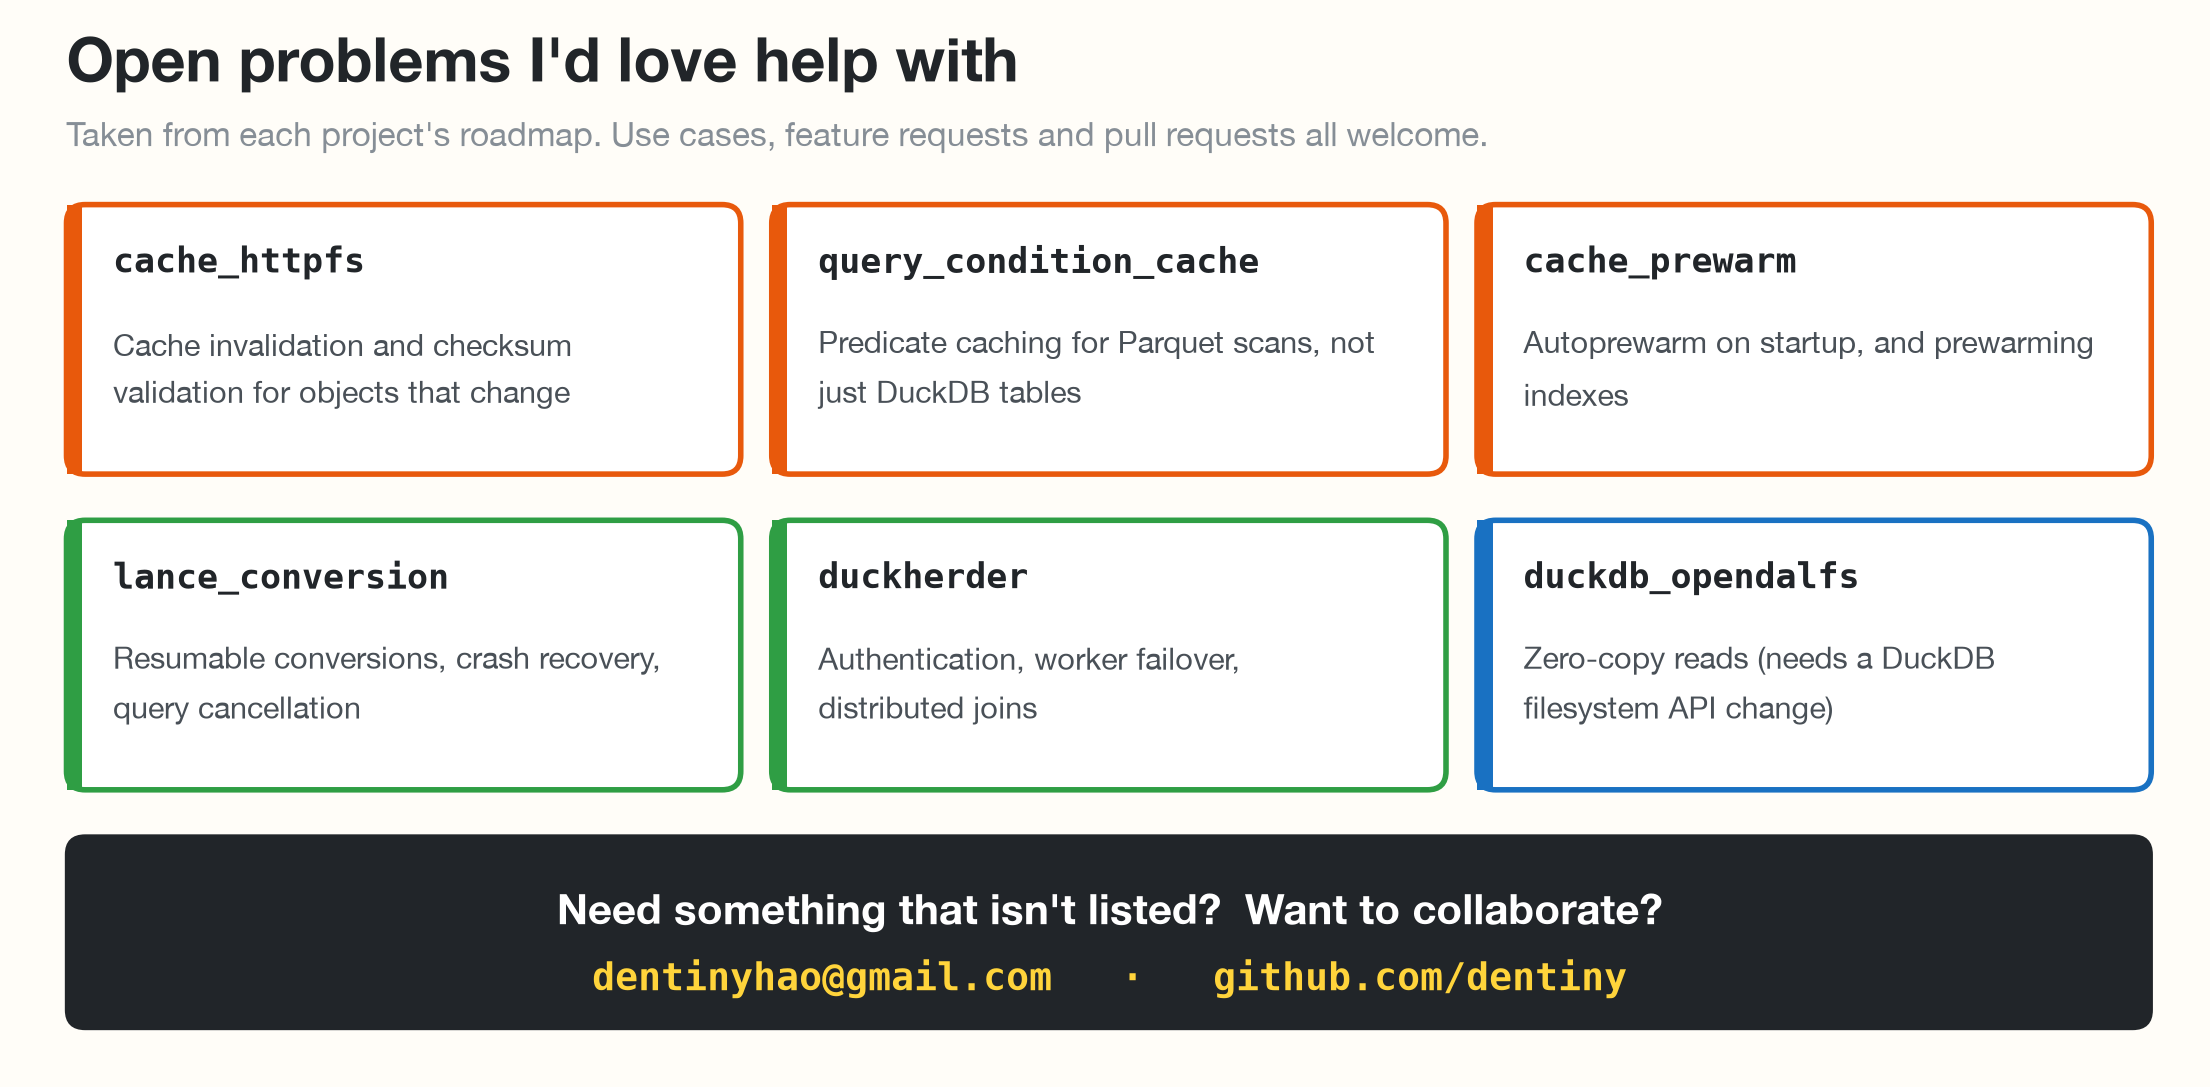
Most of these extensions started as someone’s problem: a slow dashboard, a flaky bucket, a dataset that needed to be in Lance. If you have one, I want to hear about it.
- Feature requests and bugs: open an issue in the extension’s repository (listed above).
- Collaboration: whether it’s one of the open problems above, a new extension, or running these in production at your company, email me at dentinyhao@gmail.com.
- Just using them? Tell me what works and what doesn’t. That’s usually how the next extension starts.
Thanks
Thank you to @peterxcli (cache_prewarm, duckdb_object_storage, observefs, query_condition_cache), @DouEnergy (cache_httpfs) and @Andrewtangtang (duckdb_object_storage, duckherder, query_condition_cache, table_inspector). Thanks also to the DuckDB Labs team and the community-extensions maintainers, who review these extensions and build them for every platform on every release.